

WEBVTT
00:00:00.040 --> 00:00:03.540
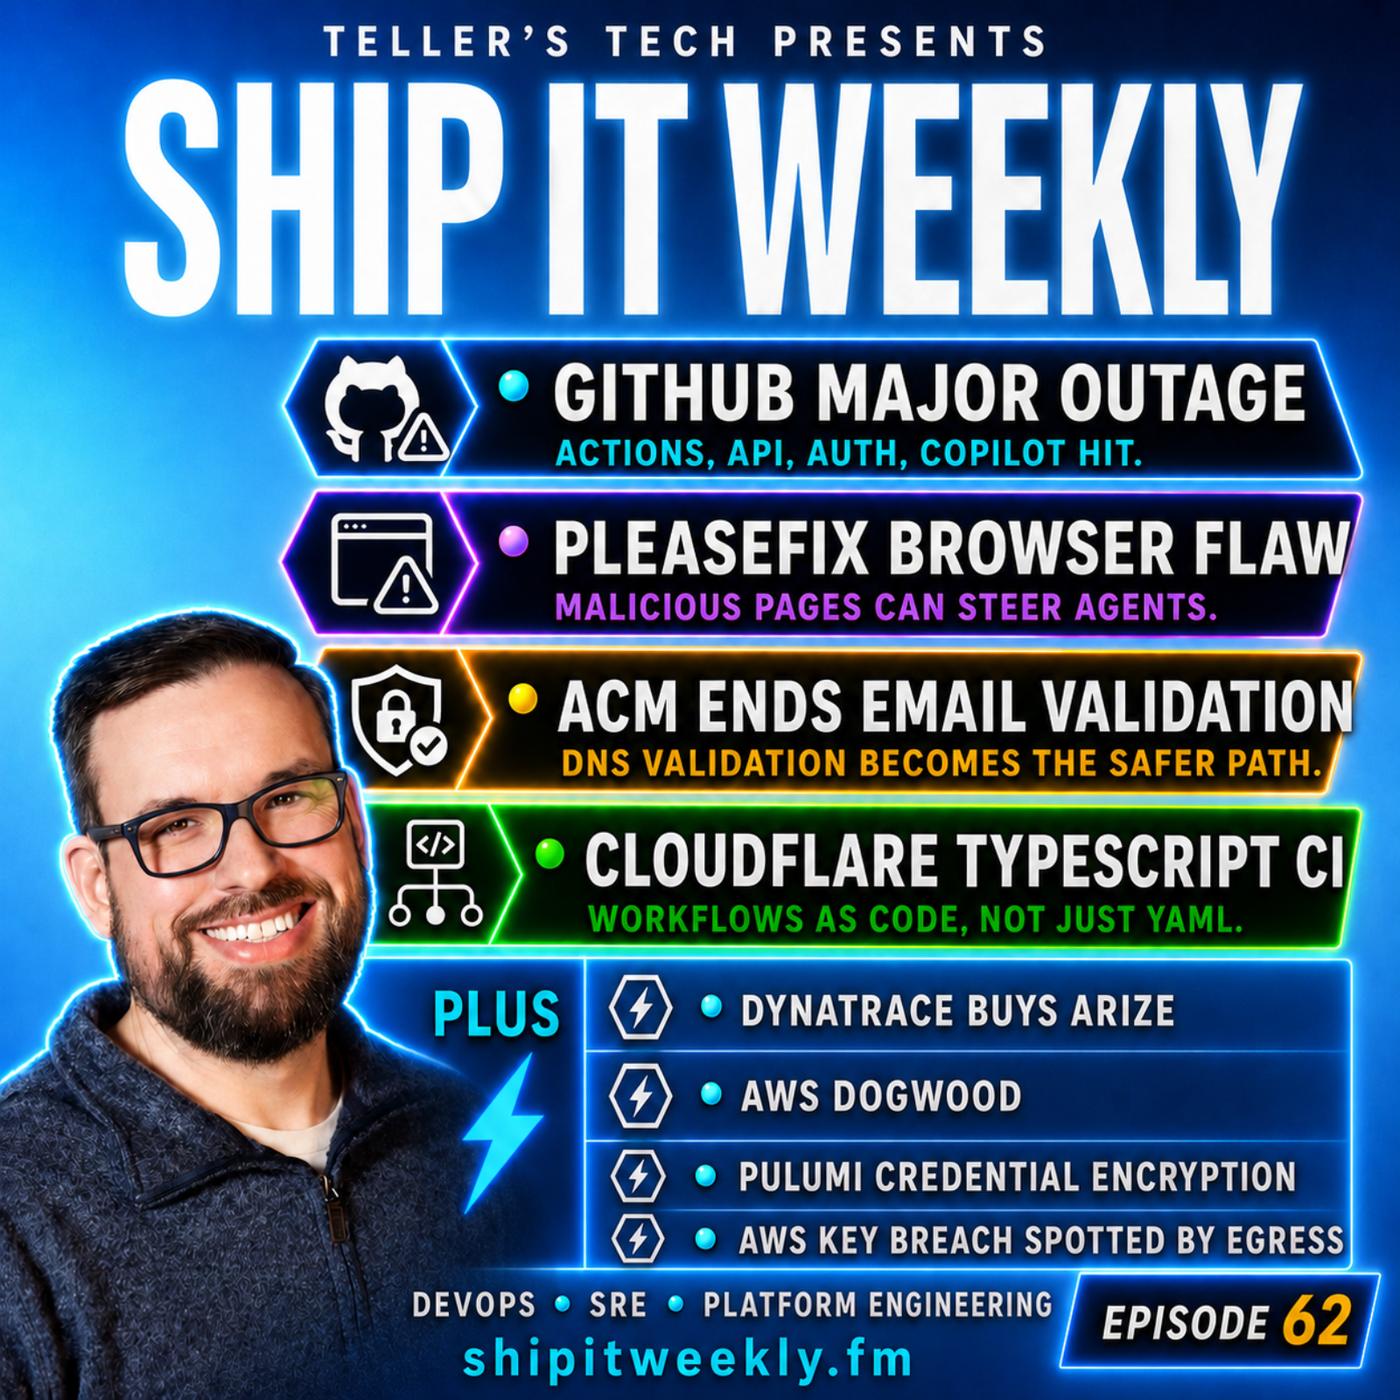
GitHub had another widespread outage this week.
00:00:03.759 --> 00:00:07.120
Agentic browsers have a vulnerability that can
00:00:07.120 --> 00:00:11.839
turn a webpage into an execution path. And AWS
00:00:11.839 --> 00:00:14.759
is finally pushing Certificate Manager users
00:00:14.759 --> 00:00:19.480
away from email validation. This week is mostly
00:00:19.480 --> 00:00:23.079
about dependencies we treat as boring until they
00:00:23.079 --> 00:00:26.140
become the incident. I'm Brian Teller from Teller's
00:00:26.140 --> 00:00:46.299
Tech, and this is Ship It Weekly. Welcome back
00:00:46.299 --> 00:00:49.000
to Ship It Weekly, the show about the DevOps,
00:00:49.299 --> 00:00:53.200
SRE, cloud, platform, and security stories that
00:00:53.200 --> 00:00:55.619
matter when you are the person keeping the thing
00:00:55.619 --> 00:00:58.420
running at three in the morning. For the weekly
00:00:58.420 --> 00:01:02.119
story list and source links, check out OnCallBrief.com. For past episodes and show notes, head
00:01:05.859 --> 00:01:09.920
over to ShipItWeekly.fm. This week, GitHub had
00:01:09.920 --> 00:01:13.469
a major outage. We have a new agentic-browser
00:01:13.469 --> 00:01:17.769
vulnerability called PleaseFix. AWS Certificate
00:01:17.769 --> 00:01:22.090
Manager is ending email validation. And Cloudflare
00:01:22.090 --> 00:01:26.250
is experimenting with TypeScript-native CI workflows.
00:01:26.709 --> 00:01:30.370
Then we have a quick lightning round and a human
00:01:30.370 --> 00:01:33.609
closer about what happens when policy changes
00:01:33.609 --> 00:01:37.409
far away from engineering still land directly
00:01:37.409 --> 00:01:40.950
on the people running production. Let's get into
00:01:40.950 --> 00:01:50.049
it. First up, GitHub had another widespread outage.
00:01:50.129 --> 00:01:54.349
The incident affected the website, API, Actions,
00:01:54.670 --> 00:01:58.109
pull requests, issues, webhooks, authentication,
00:01:58.670 --> 00:02:03.430
and Copilot. At points, web and API error rates
00:02:03.430 --> 00:02:07.650
were around 20%, with some services reportedly
00:02:07.650 --> 00:02:11.900
much worse. The obvious takeaway is that GitHub
00:02:11.900 --> 00:02:15.419
was down. The more useful one is that GitHub
00:02:15.419 --> 00:02:18.460
is not really just a developer tool anymore.
00:02:18.879 --> 00:02:22.219
For a lot of companies, GitHub sits directly
00:02:22.219 --> 00:02:26.939
in the production path. It runs CI/CD. It holds
00:02:26.939 --> 00:02:31.120
source code. It manages pull requests and approvals.
00:02:31.319 --> 00:02:34.860
It may be part of authentication. It triggers
00:02:34.860 --> 00:02:39.069
deployments. And increasingly, AI tooling depends
00:02:39.069 --> 00:02:43.330
on it too. So when GitHub has an outage, the
00:02:43.330 --> 00:02:46.250
impact is not just that engineers cannot push
00:02:46.250 --> 00:02:50.030
code. You can lose deployment capability, change
00:02:50.030 --> 00:02:53.590
management, incident automation, and sometimes
00:02:53.590 --> 00:02:57.330
even access to the thing you need in order to
00:02:57.330 --> 00:03:00.810
fix something else. That means GitHub belongs
00:03:00.810 --> 00:03:03.949
in dependency planning the same way any other
00:03:03.949 --> 00:03:07.819
critical SaaS provider does. Can you deploy if
00:03:07.819 --> 00:03:12.379
it is unavailable? Can you roll back? Can you access
00:03:12.379 --> 00:03:16.360
the last known-good artifact? Can you authenticate
00:03:16.360 --> 00:03:20.199
to the systems you need? And do your incident
00:03:20.199 --> 00:03:23.020
procedures still work if the place where your
00:03:23.020 --> 00:03:26.680
runbook lives is also having an outage? There
00:03:26.680 --> 00:03:29.419
is also a difference between being unable to
00:03:29.419 --> 00:03:33.340
ship new code and being unable to recover existing
00:03:33.340 --> 00:03:37.360
code Those are not the same risk. Maybe it is
00:03:37.360 --> 00:03:40.500
completely acceptable for deployments to stop
00:03:40.500 --> 00:03:44.219
when GitHub is unavailable. In fact, that may
00:03:44.219 --> 00:03:47.879
be safer. But rollback is different. If your
00:03:47.879 --> 00:03:51.360
rollback procedure starts by checking out a repository,
00:03:51.780 --> 00:03:55.560
running a GitHub action, or waiting for an approval
00:03:55.560 --> 00:03:59.419
inside GitHub, then your recovery path shares
00:03:59.419 --> 00:04:02.580
the same dependency as your deployment path.
00:04:03.039 --> 00:04:05.780
That is worth testing before the outage. You
00:04:05.780 --> 00:04:08.340
do not necessarily need a second source-control
00:04:08.340 --> 00:04:12.280
platform sitting around. But keeping signed artifacts
00:04:12.280 --> 00:04:15.460
somewhere independent, documenting emergency
00:04:15.460 --> 00:04:19.800
deployment procedures, and knowing exactly which
00:04:19.800 --> 00:04:23.060
parts of your recovery path depend on GitHub
00:04:23.060 --> 00:04:27.139
can make a huge difference. Developer infrastructure
00:04:27.139 --> 00:04:30.639
is production infrastructure now. Treating it
00:04:30.639 --> 00:04:39.110
otherwise is mostly wishful thinking. Next,
00:04:39.410 --> 00:04:43.269
there is a vulnerability called PleaseFix affecting
00:04:43.269 --> 00:04:46.670
agentic browsers. The core issue is that the
00:04:46.670 --> 00:04:49.529
browser is no longer just displaying content.
00:04:49.810 --> 00:04:53.610
An agentic browser can interpret content, make
00:04:53.610 --> 00:04:57.870
decisions, use tools, and take actions. That
00:04:57.870 --> 00:05:00.649
changes the threat model. A malicious webpage
00:05:01.209 --> 00:05:04.029
is not only trying to trick a person anymore.
00:05:04.370 --> 00:05:08.250
It may be trying to influence an autonomous system
00:05:08.250 --> 00:05:11.569
that has access to credentials, local files,
00:05:11.990 --> 00:05:16.529
cloud services, or external APIs. That is a very
00:05:16.529 --> 00:05:19.129
different boundary. The interesting part here
00:05:19.129 --> 00:05:23.189
is not whether the model is smart enough to recognize
00:05:23.189 --> 00:05:27.350
a bad instruction. The interesting part is whether
00:05:27.350 --> 00:05:30.759
the surrounding system allows that instruction
00:05:30.759 --> 00:05:35.180
to become an action. If a webpage can indirectly
00:05:35.180 --> 00:05:39.800
cause the agent to run a command, submit data,
00:05:40.000 --> 00:05:44.279
or interact with another service, then the browser
00:05:44.279 --> 00:05:47.600
has effectively become part of your execution
00:05:47.600 --> 00:05:50.980
environment. And that means the same controls
00:05:50.980 --> 00:05:55.680
we use everywhere else still matter. Scoped credentials.
00:05:56.199 --> 00:05:59.600
Tool-level permissions. network restrictions,
00:05:59.959 --> 00:06:04.699
human approval for sensitive actions, and a clean
00:06:04.699 --> 00:06:09.220
separation between untrusted content and privileged
00:06:09.220 --> 00:06:13.240
operations. I also think this is where the phrase
00:06:13.240 --> 00:06:17.420
human-in-the-loop gets oversold. A confirmation
00:06:17.420 --> 00:06:21.519
dialog is useful, but if the agent controls
00:06:21.519 --> 00:06:25.480
the text surrounding that confirmation, summarizes
00:06:25.480 --> 00:06:29.040
the action for the user, or performs enough harmless-looking steps before asking for approval, then
00:06:32.779 --> 00:06:37.120
clicking yes can become almost automatic. The
00:06:37.120 --> 00:06:40.379
better control is to make high-risk actions
00:06:40.379 --> 00:06:44.579
technically distinct. Reading a webpage should
00:06:44.579 --> 00:06:48.839
not implicitly grant the ability to upload a
00:06:48.839 --> 00:06:52.860
local file. Summarizing an issue should not grant
00:06:52.860 --> 00:06:56.980
the ability to merge a pull request. Browsing
00:06:56.980 --> 00:07:00.060
documentation should not grant shell access.
00:07:00.420 --> 00:07:04.019
Those boundaries should exist outside the model.
00:07:04.279 --> 00:07:07.680
We keep talking about prompt injection like it
00:07:07.680 --> 00:07:11.000
is a weird AI-specific problem. A lot of the
00:07:11.000 --> 00:07:14.660
time, it is really an authorization problem wearing
00:07:14.660 --> 00:07:19.199
new clothes. The input is untrusted, the action
00:07:19.199 --> 00:07:22.800
is privileged, and there is not enough enforcement
00:07:22.800 --> 00:07:31.350
between the two. Third, AWS Certificate Manager
00:07:31.350 --> 00:07:35.990
is ending support for email validation for new
00:07:35.990 --> 00:07:40.029
public certificates. DNS validation is becoming
00:07:40.029 --> 00:07:43.990
the path forward. That sounds boring. It is also
00:07:43.990 --> 00:07:47.430
exactly the kind of boring change that breaks
00:07:47.430 --> 00:07:50.509
things months later because nobody remembers
00:07:50.509 --> 00:07:54.310
which certificate still depends on an old workflow.
00:07:54.779 --> 00:07:58.819
Email validation has always been awkward operationally.
00:07:58.939 --> 00:08:01.860
Someone has to receive the validation message.
00:08:02.139 --> 00:08:06.040
The right mailbox has to exist. The right person
00:08:06.040 --> 00:08:09.540
has to notice it. And renewals can depend on
00:08:09.540 --> 00:08:13.019
that process continuing to work. DNS validation
00:08:13.019 --> 00:08:17.420
is much easier to automate and much easier to
00:08:17.420 --> 00:08:20.959
make durable. This also lines up with another
00:08:20.959 --> 00:08:24.310
recurring theme from this week. Certificate
00:08:24.310 --> 00:08:28.170
expiry is still causing real outages, which is
00:08:28.170 --> 00:08:32.570
kind of amazing in 2026. Certificates are predictable.
00:08:32.850 --> 00:08:35.990
They have expiration dates. They are machine-readable. And yet, teams still get surprised
00:08:39.470 --> 00:08:43.090
by them. Usually, the problem is not the certificate
00:08:43.090 --> 00:08:47.649
itself. It is ownership. Nobody knows who owns
00:08:47.649 --> 00:08:51.169
the domain. The renewal process depends on an
00:08:51.169 --> 00:08:55.059
old mailbox. A certificate was created manually
00:08:55.059 --> 00:08:58.700
years ago. Or the monitoring only checks the
00:08:58.700 --> 00:09:02.120
application after the certificate has already
00:09:02.120 --> 00:09:06.120
expired. Another trap is monitoring only the
00:09:06.120 --> 00:09:08.840
certificate you think production is serving.
00:09:09.039 --> 00:09:12.320
There may be a load balancer with one certificate,
00:09:12.600 --> 00:09:16.200
a CDN with another, an internal service mesh
00:09:16.200 --> 00:09:19.750
issuing its own certificates, and some forgotten
00:09:19.750 --> 00:09:22.570
endpoint using something completely different.
00:09:22.769 --> 00:09:26.610
The useful inventory is not just what certificates
00:09:26.610 --> 00:09:31.269
exist. It is which endpoint presents which certificate,
00:09:31.610 --> 00:09:35.809
who renews it, and what happens if renewal fails.
00:09:36.129 --> 00:09:39.870
That is a much more operational question. The
00:09:39.870 --> 00:09:43.289
fix is not complicated. Inventory the certificates.
00:09:43.629 --> 00:09:47.610
Know who owns them. Automate renewal where possible.
00:09:48.139 --> 00:09:51.500
Alert well before expiration, and test the renewal
00:09:51.500 --> 00:09:54.919
path before the deadline. Certificate management
00:09:54.919 --> 00:09:58.460
is one of those areas where boring automation
00:09:58.460 --> 00:10:02.700
is dramatically better than heroic incident response.
00:10:07.399 --> 00:10:12.000
Fourth, Cloudflare is experimenting with CI workflows
00:10:12.000 --> 00:10:16.470
written in TypeScript. The interesting idea is
00:10:16.470 --> 00:10:19.909
that the workflow itself becomes normal application
00:10:19.909 --> 00:10:24.549
code. You can define steps, retries, concurrency,
00:10:24.730 --> 00:10:28.629
and caching behavior in TypeScript instead of
00:10:28.629 --> 00:10:32.070
expressing everything through a large YAML configuration.
00:10:32.710 --> 00:10:36.269
There are some obvious advantages. You get normal
00:10:36.269 --> 00:10:40.110
language constructs. And you can test parts of
00:10:40.110 --> 00:10:43.269
the workflow more like software. But there is
00:10:43.269 --> 00:10:46.789
also a tradeoff. The more programmable CI becomes,
00:10:47.149 --> 00:10:50.970
the easier it is for the pipeline to turn into
00:10:50.970 --> 00:10:54.809
another application nobody really owns. We have
00:10:54.809 --> 00:10:58.509
all seen YAML pipelines become impossible to
00:10:58.509 --> 00:11:02.250
reason about. Code can absolutely become impossible
00:11:02.250 --> 00:11:05.649
to reason about too. There is also a governance
00:11:05.649 --> 00:11:09.250
question here. One advantage of declarative CI
00:11:09.250 --> 00:11:13.190
is that the set of things a pipeline can express
00:11:13.820 --> 00:11:17.120
is intentionally constrained. Once workflows
00:11:17.120 --> 00:11:20.299
become arbitrary code, you gain flexibility.
00:11:20.740 --> 00:11:24.000
But you also need stronger conventions around
00:11:24.000 --> 00:11:28.200
libraries, reviews, dependency management, and
00:11:28.200 --> 00:11:32.399
security. Otherwise, every team eventually invents
00:11:32.399 --> 00:11:36.159
its own tiny workflow framework. So, I do not
00:11:36.159 --> 00:11:39.220
think that the lesson is that YAML is bad and
00:11:39.220 --> 00:11:42.870
TypeScript is good. The lesson is that CI
00:11:42.870 --> 00:11:46.690
systems are software systems. They need structure.
00:11:47.009 --> 00:11:51.830
They need tests. They need clear ownership. They
00:11:51.830 --> 00:11:55.669
need versioning. And they need enough observability
00:11:55.669 --> 00:11:59.990
that someone can understand why step seven retried
00:11:59.990 --> 00:12:04.370
four times and then deployed anyway. If CI is
00:12:04.370 --> 00:12:07.450
part of your production delivery path, treating
00:12:07.450 --> 00:12:11.370
the workflow definition like real software makes
00:12:11.370 --> 00:12:15.690
a lot of sense. Just remember that real software
00:12:15.690 --> 00:12:26.950
also comes with maintenance. Quick lightning
00:12:26.950 --> 00:12:31.509
round. First, Dynatrace is acquiring Arize for
00:12:31.509 --> 00:12:37.070
about $915 million. That is another sign that
00:12:37.070 --> 00:12:40.649
AI observability is becoming part of the mainstream
00:12:40.649 --> 00:12:44.190
observability platform instead of living in a
00:12:44.190 --> 00:12:48.549
separate niche. Second, AWS open-sourced Dogwood
00:12:48.549 --> 00:12:51.909
for governing agent tool calls. The interesting
00:12:51.909 --> 00:12:57.049
part is policy around what an agent can do, when
00:12:57.049 --> 00:13:01.049
it can do it, and under what conditions. That
00:13:01.049 --> 00:13:05.309
fits directly with the PleaseFix story. Third,
00:13:05.549 --> 00:13:10.419
Pulumi 3.258 adds opt-in credential encryption.
00:13:10.840 --> 00:13:15.139
Small change, but a useful reminder that IaC
00:13:15.139 --> 00:13:19.360
state and configuration often contain more sensitive
00:13:19.360 --> 00:13:23.639
material than teams realize. And fourth, one
00:13:23.639 --> 00:13:26.840
AWS credential breach was reportedly noticed
00:13:26.840 --> 00:13:31.100
because the bill changed. Unexpected egress charges
00:13:31.100 --> 00:13:35.879
became the security signal. FinOps data is not
00:13:35.879 --> 00:13:39.629
just about cost anymore. Sometimes it is telemetry
00:13:39.629 --> 00:13:51.210
for compromise. The human closer this week comes
00:13:51.210 --> 00:13:55.610
from a story titled Mario saved the EU but broke
00:13:55.610 --> 00:13:59.389
my system. The details are pretty fun, but the
00:13:59.389 --> 00:14:02.409
part I liked is the familiar engineering experience
00:14:02.409 --> 00:14:06.190
underneath it. A policy or platform decision
00:14:06.830 --> 00:14:10.309
gets made somewhere far away from the team operating
00:14:10.309 --> 00:14:14.289
the system. The change may be reasonable. It
00:14:14.289 --> 00:14:18.470
may even be the right thing to do. But the operational
00:14:18.470 --> 00:14:22.970
consequences still land on somebody. That somebody
00:14:22.970 --> 00:14:26.610
is usually an engineer who did not write the
00:14:26.610 --> 00:14:30.649
policy, did not choose the deadline, and still
00:14:30.649 --> 00:14:34.110
has to make production work afterward. That happens
00:14:34.110 --> 00:14:37.659
with regulations. Security requirements, browser
00:14:37.659 --> 00:14:41.419
changes, cloud provider defaults, certificate
00:14:41.419 --> 00:14:46.240
rules, and internal compliance projects. From
00:14:46.240 --> 00:14:49.759
the outside the change can look simple. From
00:14:49.759 --> 00:14:52.960
the inside it can touch identity, networking,
00:14:53.299 --> 00:14:57.379
billing, deployment, observability, and a pile
00:14:57.379 --> 00:15:01.039
of assumptions nobody documented. I think that
00:15:01.039 --> 00:15:03.940
is one of the underrated parts of infrastructure
00:15:03.940 --> 00:15:08.299
work. You spend a lot of time translating decisions
00:15:08.299 --> 00:15:12.799
made at one layer into consequences at another.
00:15:13.080 --> 00:15:16.759
And sometimes the hardest part is not technical
00:15:16.759 --> 00:15:20.899
at all. It is explaining that a change described
00:15:20.899 --> 00:15:25.059
as one checkbox in a compliance document might
00:15:25.059 --> 00:15:28.980
actually require three teams, a migration plan,
00:15:29.320 --> 00:15:33.480
downtime coordination, and six weeks of testing.
00:15:33.960 --> 00:15:37.120
That is not engineers being difficult. That is
00:15:37.120 --> 00:15:39.299
the difference between describing an outcome
00:15:39.299 --> 00:15:43.320
and implementing it safely. The best platform
00:15:43.320 --> 00:15:46.580
and infrastructure teams get good at making that
00:15:46.580 --> 00:15:50.419
translation visible early, not after the deadline,
00:15:50.659 --> 00:15:54.600
not after the outage. Early enough that everyone
00:15:54.600 --> 00:15:58.480
understands what the change actually costs. And
00:15:58.480 --> 00:16:02.220
the best engineers are usually the ones who can
00:16:02.220 --> 00:16:05.600
do that without turning every change into a
00:16:05.600 --> 00:16:09.720
fight. Understand why the change exists. Figure
00:16:09.720 --> 00:16:13.840
out where the blast radius actually is. Communicate
00:16:13.840 --> 00:16:17.159
the tradeoffs clearly. And make the transition
00:16:17.159 --> 00:16:22.039
boring. That is usually the real job. Not preventing
00:16:22.039 --> 00:16:26.620
change. Making change survivable. That's it for
00:16:26.620 --> 00:16:30.259
this week of Ship It Weekly. We covered GitHub's
00:16:30.259 --> 00:16:33.789
outage, the PleaseFix agentic-browser vulnerability,
00:16:34.049 --> 00:16:37.789
AWS Certificate Manager moving away from email
00:16:37.789 --> 00:16:42.570
validation, and Cloudflare's TypeScript CI workflows,
00:16:42.990 --> 00:16:48.750
plus Dynatrace and Arize, AWS Dogwood, Pulumi
00:16:48.750 --> 00:16:53.230
credential encryption, and an AWS breach detected
00:16:53.230 --> 00:16:57.629
through unexpected egress costs. Follow or subscribe
00:16:57.629 --> 00:17:01.190
wherever you are watching or listening. You can
00:17:01.190 --> 00:17:04.710
find the weekly story list and source links at
00:17:04.710 --> 00:17:09.250
OnCallBrief.com and past episodes and full show
00:17:09.250 --> 00:17:13.430
notes at ShipItWeekly.fm. I'm Brian Teller from
00:17:13.430 --> 00:17:16.369
Teller's Tech. Thanks for listening. And remember,
00:17:16.609 --> 00:17:20.730
the boring dependency is usually boring right
00:17:20.730 --> 00:17:23.269
up until it becomes the whole incident.
