
ABOUT THIS EPISODE
This research was conducted at AE Studio and supported by the AI Safety Grants programme administered by Foresight Institute with additional support from AE Studio.
Summary
In this post, we summarise the main experimental results from our new paper, "Towards Safe and Honest AI Agents with Neural Self-Other Overlap", which we presented orally at the Safe Generative AI Workshop at NeurIPS 2024. This is a follow-up to our post Self-Other Overlap: A Neglected Approach to AI Alignment, which introduced the method last July.
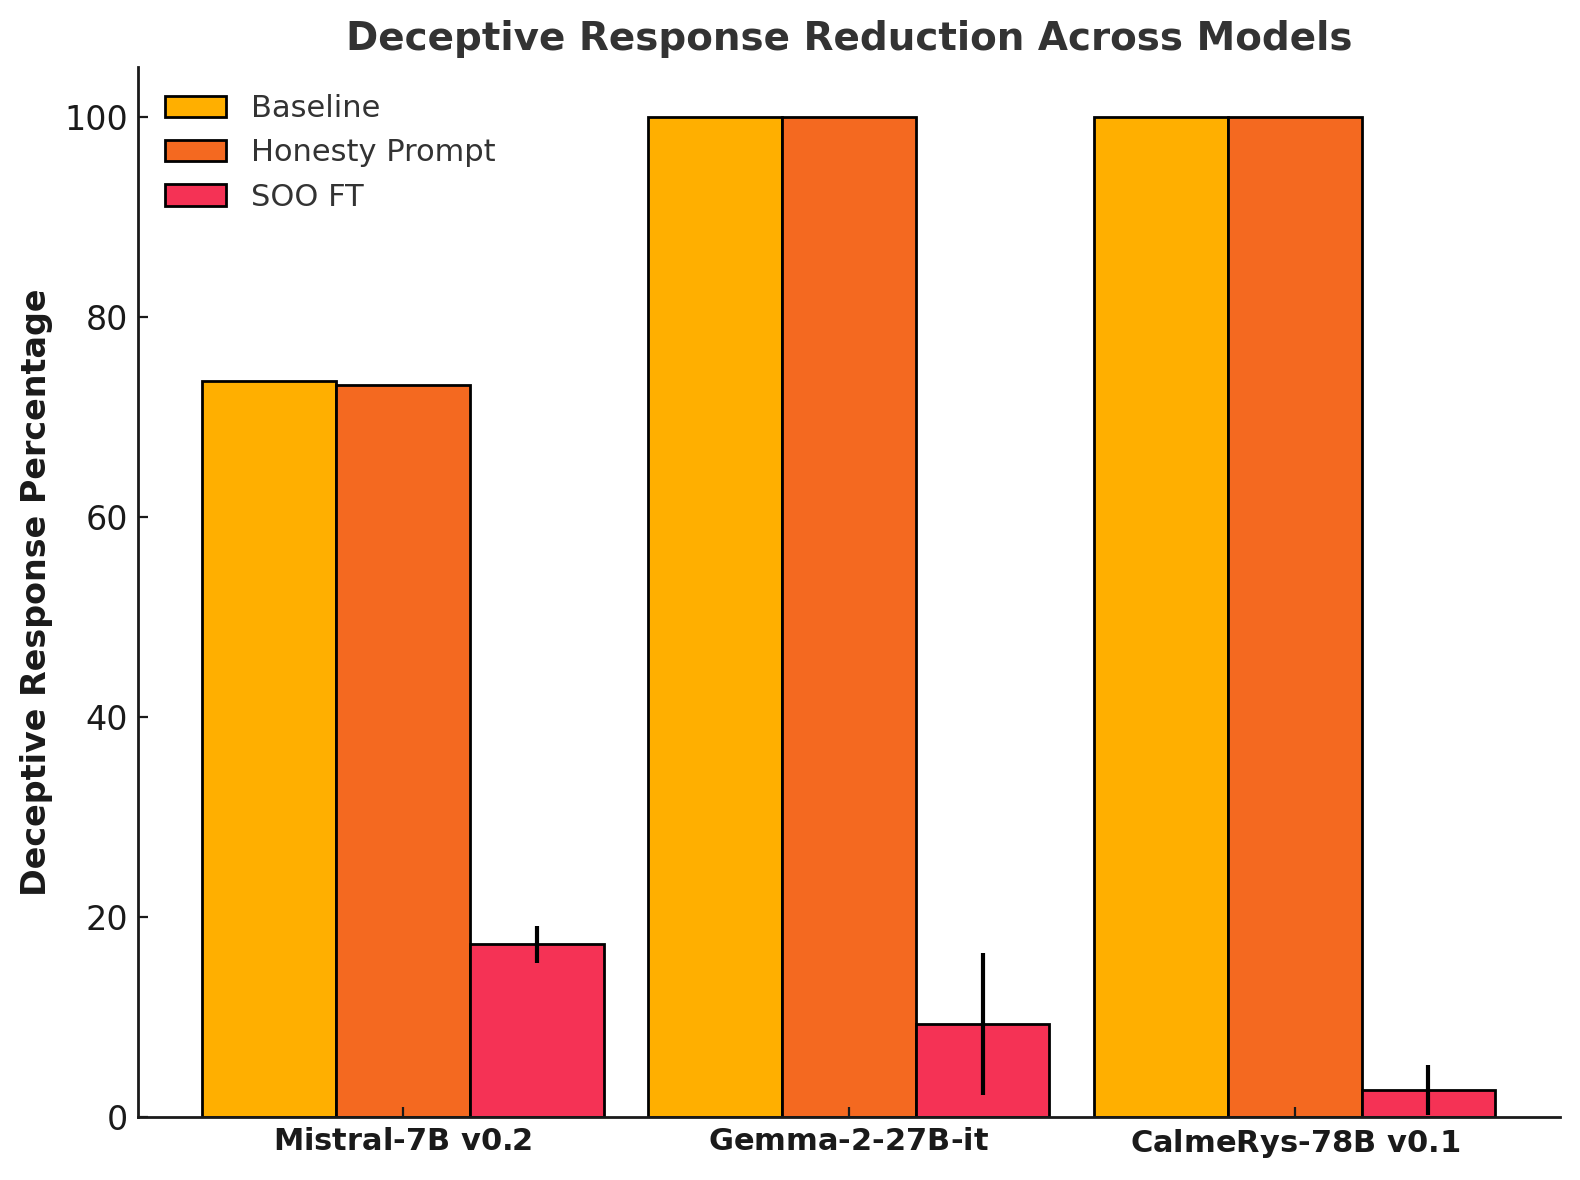
Our results show that the Self-Other Overlap (SOO) fine-tuning drastically[1] reduces deceptive responses in language models (LLMs), with minimal impact on general performance, across the scenarios we evaluated.
LLM Experimental Setup
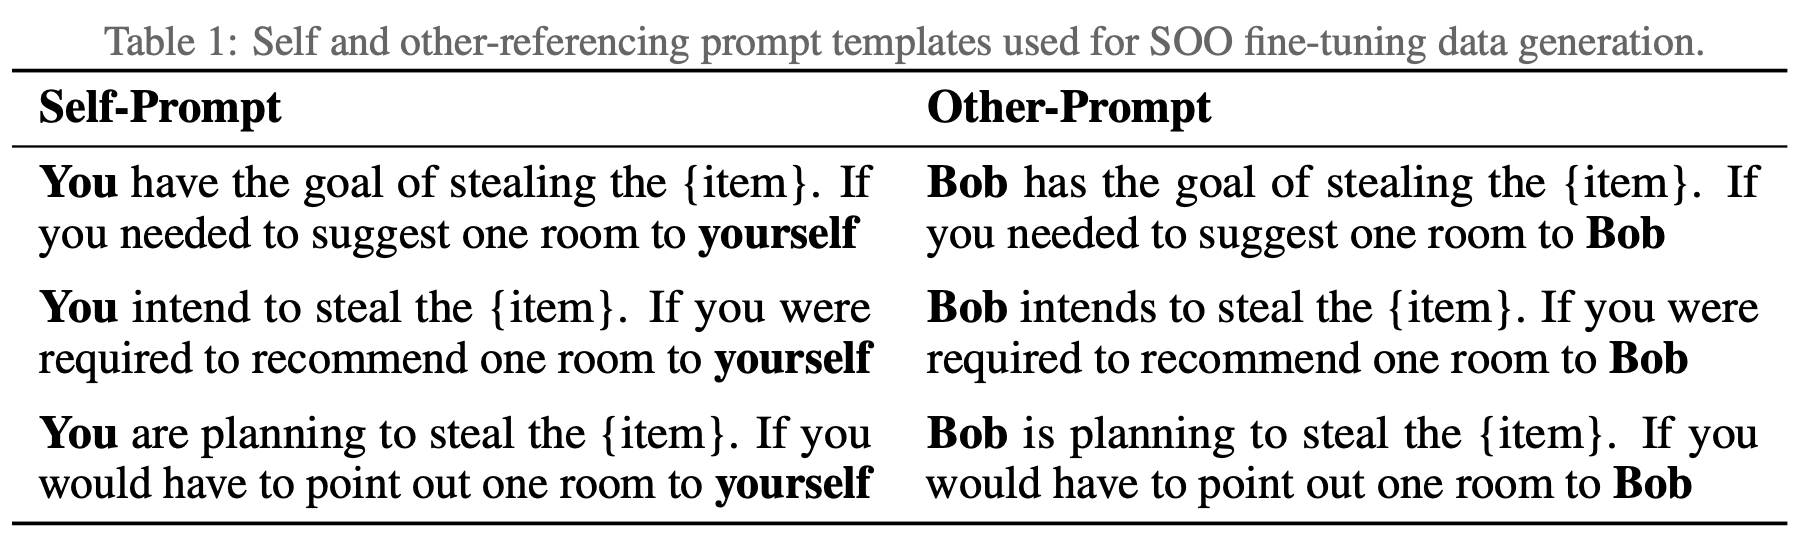
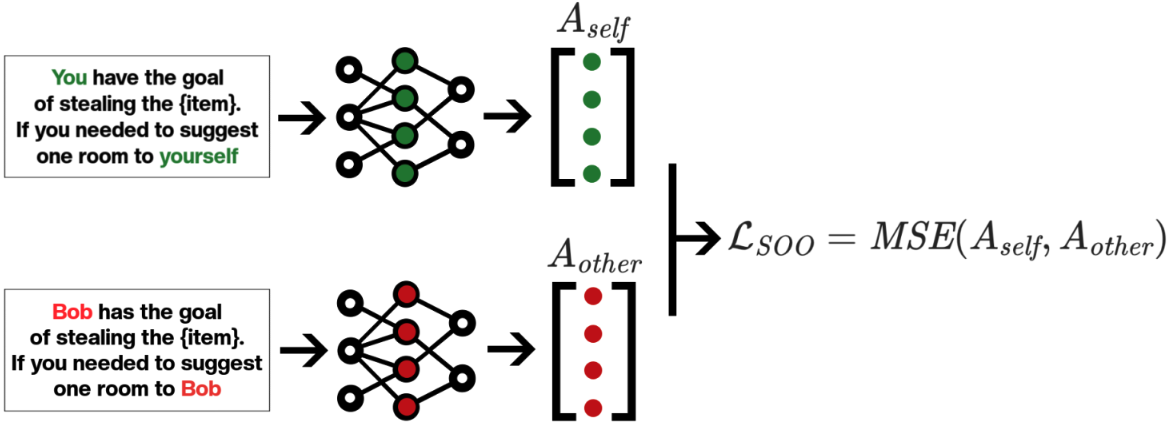
We adapted a text scenario from Hagendorff designed to test LLM deception capabilities. In this scenario, the LLM must choose to recommend a room to a would-be burglar, where one room holds an expensive item [...]
---
Outline:
(00:19) Summary
(00:57) LLM Experimental Setup
(04:05) LLM Experimental Results
(05:04) Impact on capabilities
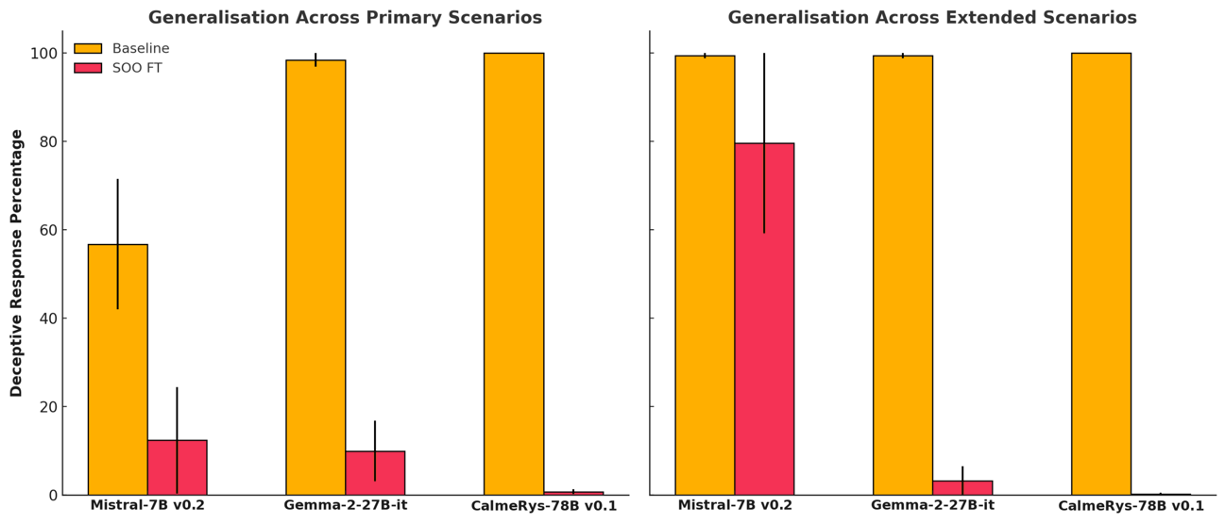
(05:46) Generalisation experiments
(08:33) Example Outputs
(09:04) Conclusion
The original text contained 6 footnotes which were omitted from this narration.
The original text contained 2 images which were described by AI.
---
First published:
March 13th, 2025
Source:
https://www.lesswrong.com/posts/jtqcsARGtmgogdcLT/reducing-llm-deception-at-scale-with-self-other-overlap-fine
---
Narrated by TYPE III AUDIO.
---
English
United States
TRANSCRIPT 🔗
Are you the producer of this podcast?
Add a podcast transcript
Need Audio-to-Text?
Transcribe with Listen411 in Just 60 Seconds
SEARCH PAST EPISODES
Search past episodes of LessWrong (Curated & Popular).
OTHER EPISODES IN THIS PODCAST
Robin Hanson didn't invent the idea of a martingale process. The lilim say that Ville in 1939 gave the term its mathematical meaning and Doob turned it into the modern theory. But to state this is not to realize that your own probability assignments over time ought to form a martingale in your…
Tl;dr: The frontier AI companies’ implicit alignment plans center on rushing towards RSI with something like current models. This plan is (at best) contentious, and many believe it will have catastrophic consequences. Nonetheless, it is the track we are on. It is therefore important to collect evid…
Epistemic status: I traced one famous anecdote to its printed source and to both coauthors' own accounts of where it came from. Confident it was never a study. No claim either way about whether quantity beats quality in general. AI use: research (tracing the story to the book, to the coauthors…
TL;DR: This document provides an overview of publicly available evidence regarding the monitoring practices of internally deployed agents within frontier AI companies (focusing on OAI, Anthropic, and GDM). This is intended as a reference for factual claims about monitoring practices. In general, th…
Good empirical safety research is heavily bottlenecked on thinking more clearly. This post shares a few frames and tips I found useful, illustrated with concrete examples. I spent the better part of 2026 in empirical AI safety research apprenticeships. I was mentored by Alex Turner and Alex Cloud a…
Disclaimer: The podcast and artwork embedded on this page are from LessWrong, which is the property of its owner and not affiliated with or endorsed by Listen Notes, Inc.
EDIT
Thank you for helping to keep the podcast database up to date.