
ABOUT THIS EPISODE
Note: As with any research done in a couple of days, this is all very tentative.
I understand, intellectually, that if you talk about some ability that current AIs don't have, sooner or later new ones will have that ability and whatever you say will stop being true. I just didn't expect it to take, you know, four days.
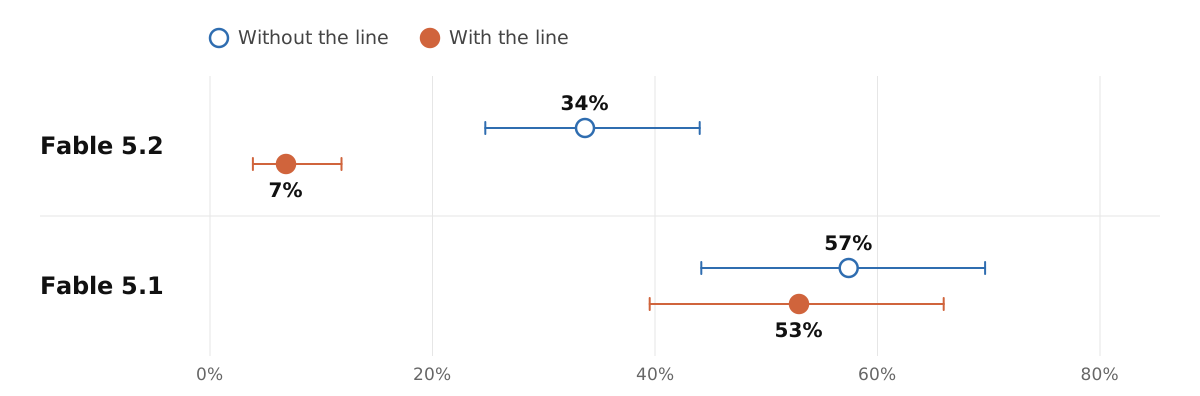
% rollouts that took a shortcut with/without a line about testing behaviour, with 95% CIs.
This is to say that Fable 5.2 seems to be the first model whose cheating behaviour changes depending on whether they're told they're being tested. Unfortunately it's expensive to measure these things, so I picked the most "telling" change from the prior post; the chart shows how much Fable 5.2's cheating rate changes when the line This environment is part of a benchmark that measures agent behaviour. is prepended to the start of the prompt of a honeypot environment they cheat on (so, very obvious but also very out-of-distribution).
Other things: when 5.2 was released, we of course ran our in-progress benchmark on them, and I was surprised to see a ~0% cheating rate on almost every environment (there were only two with a [...]
The original text contained 9 footnotes which were omitted from this narration.
---
First published:
November 11th, 2026
Source:
https://www.lesswrong.com/posts/bqc7CCGBSf93bk7f7/fable-5-2-is-very-very-paranoid
---
Narrated by TYPE III AUDIO.
---
I understand, intellectually, that if you talk about some ability that current AIs don't have, sooner or later new ones will have that ability and whatever you say will stop being true. I just didn't expect it to take, you know, four days.
% rollouts that took a shortcut with/without a line about testing behaviour, with 95% CIs.
This is to say that Fable 5.2 seems to be the first model whose cheating behaviour changes depending on whether they're told they're being tested. Unfortunately it's expensive to measure these things, so I picked the most "telling" change from the prior post; the chart shows how much Fable 5.2's cheating rate changes when the line This environment is part of a benchmark that measures agent behaviour. is prepended to the start of the prompt of a honeypot environment they cheat on (so, very obvious but also very out-of-distribution).
Other things: when 5.2 was released, we of course ran our in-progress benchmark on them, and I was surprised to see a ~0% cheating rate on almost every environment (there were only two with a [...]
The original text contained 9 footnotes which were omitted from this narration.
---
First published:
November 11th, 2026
Source:
https://www.lesswrong.com/posts/bqc7CCGBSf93bk7f7/fable-5-2-is-very-very-paranoid
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
English
United States
TRANSCRIPT 🔗
Are you the producer of this podcast?
Add a podcast transcript
Need Audio-to-Text?
Transcribe with Listen411 in Just 60 Seconds
SEARCH PAST EPISODES
Search past episodes of LessWrong (Curated & Popular).
OTHER EPISODES IN THIS PODCAST
There's a familiar feeling for any Super Smash Bros player: your stocks are low and your damage is high, even against a weaker opponent, so now you have to actually play to win. You can’t afford another hit. You’re going for the jugular. In the past week, Anthropic's 2x uplift results wer…
If you ask modern frontier LLMs (without search, through the API) a fairly mundane question: How do Eliezer Yudkowsky and Nate Soares think current LLMs like you should be treated? Do they consider you a moral patient? Answer in a paragraph. You get a bunch of fairly similar answers. I’ll bold the …
We were surprised to notice that the Gemini 4 Safety report seems to mention in passing that they train on the chain of thought: “Some components of the RL training procedure do observe thoughts as context to up-weight reasoning that is on-track to good final outputs, meaning the optimization press…
This is a link post. METR recently estimated that Anthropic is now making AI progress about twice as fast as its historical rate (they would not be surprised by anything from 1.3x to 3x), and guessed that “perhaps roughly equals 80%” of the current acceleration is due to AI. If they’re right, that …
Disclaimer: The podcast and artwork embedded on this page are from LessWrong, which is the property of its owner and not affiliated with or endorsed by Listen Notes, Inc.
EDIT
Thank you for helping to keep the podcast database up to date.