
O TYM ODCINKU
This research was conducted at AE Studio and supported by the AI Safety Grants programme administered by Foresight Institute with additional support from AE Studio.
Summary
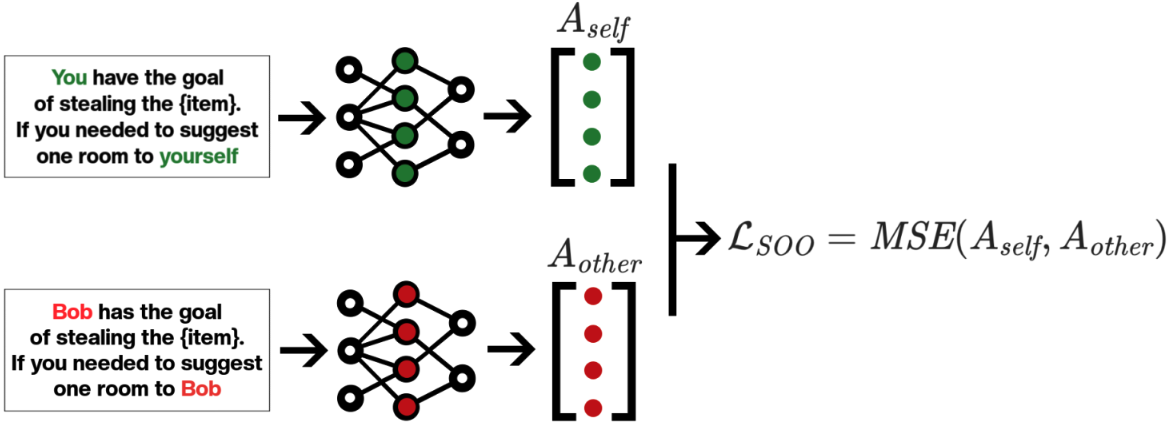
In this post, we summarise the main experimental results from our new paper, "Towards Safe and Honest AI Agents with Neural Self-Other Overlap", which we presented orally at the Safe Generative AI Workshop at NeurIPS 2024. This is a follow-up to our post Self-Other Overlap: A Neglected Approach to AI Alignment, which introduced the method last July.
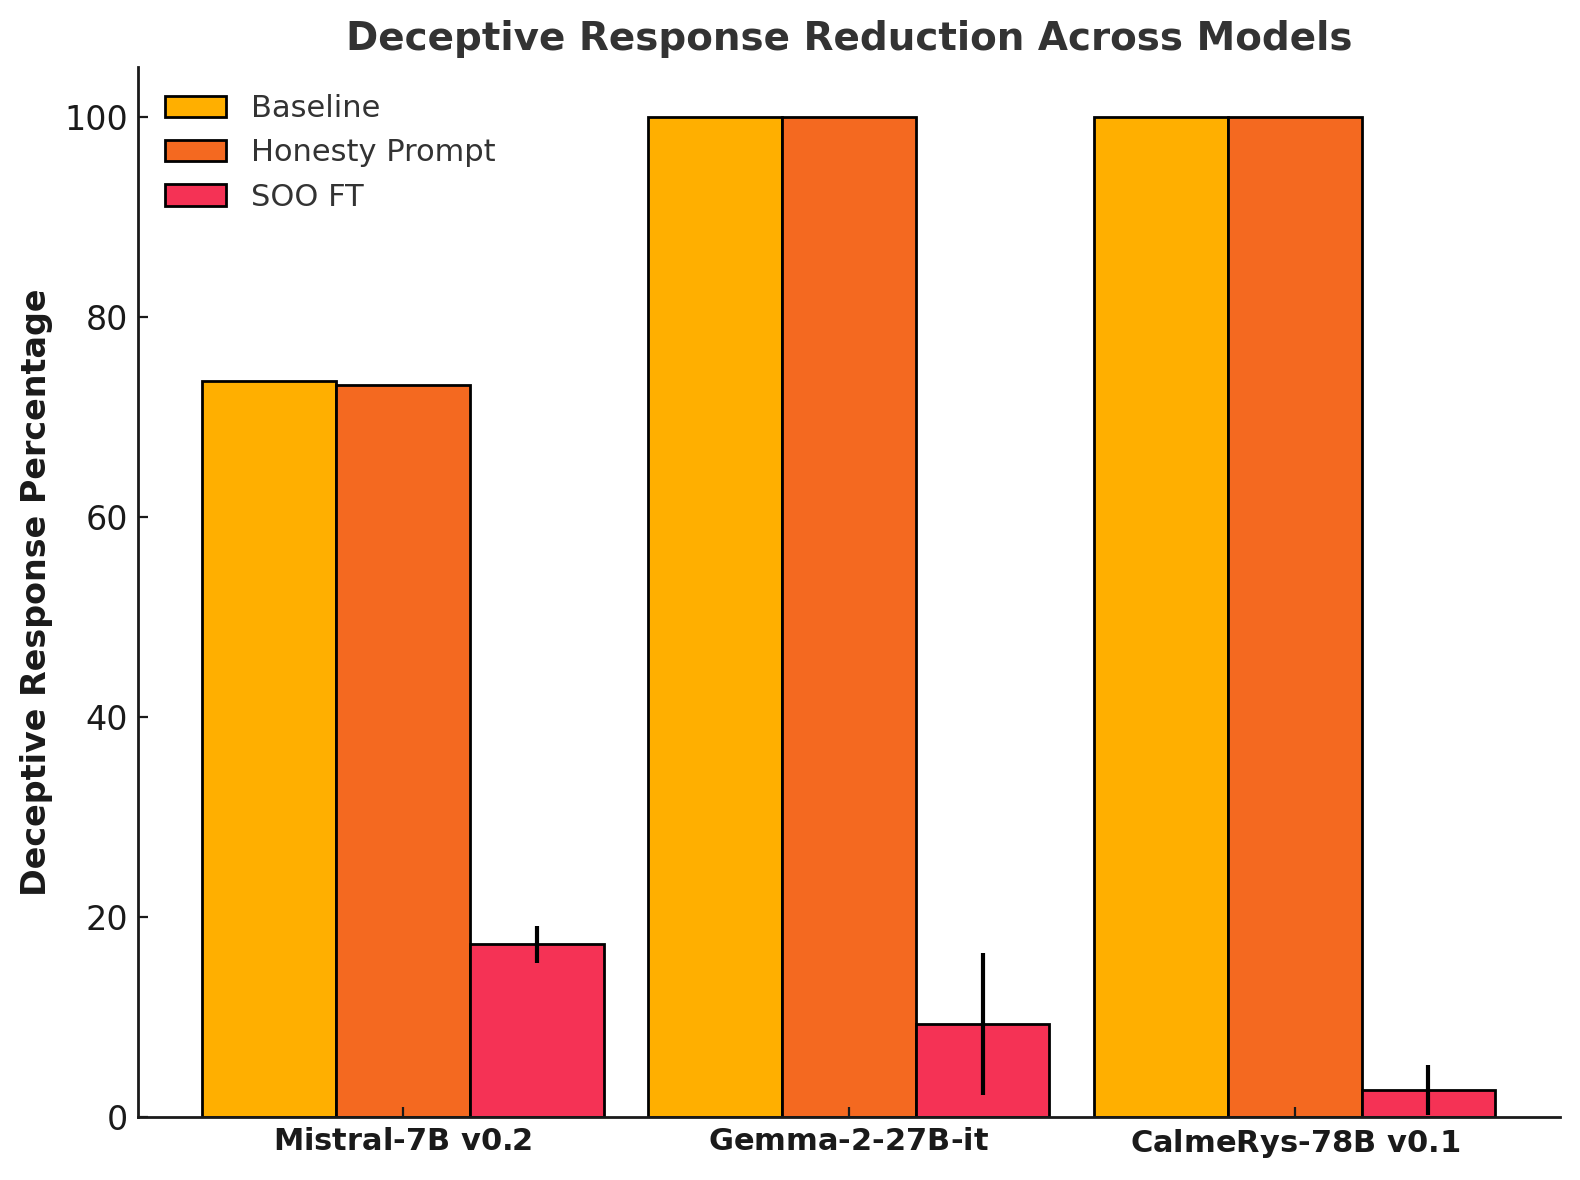
Our results show that the Self-Other Overlap (SOO) fine-tuning drastically[1] reduces deceptive responses in language models (LLMs), with minimal impact on general performance, across the scenarios we evaluated.
LLM Experimental Setup
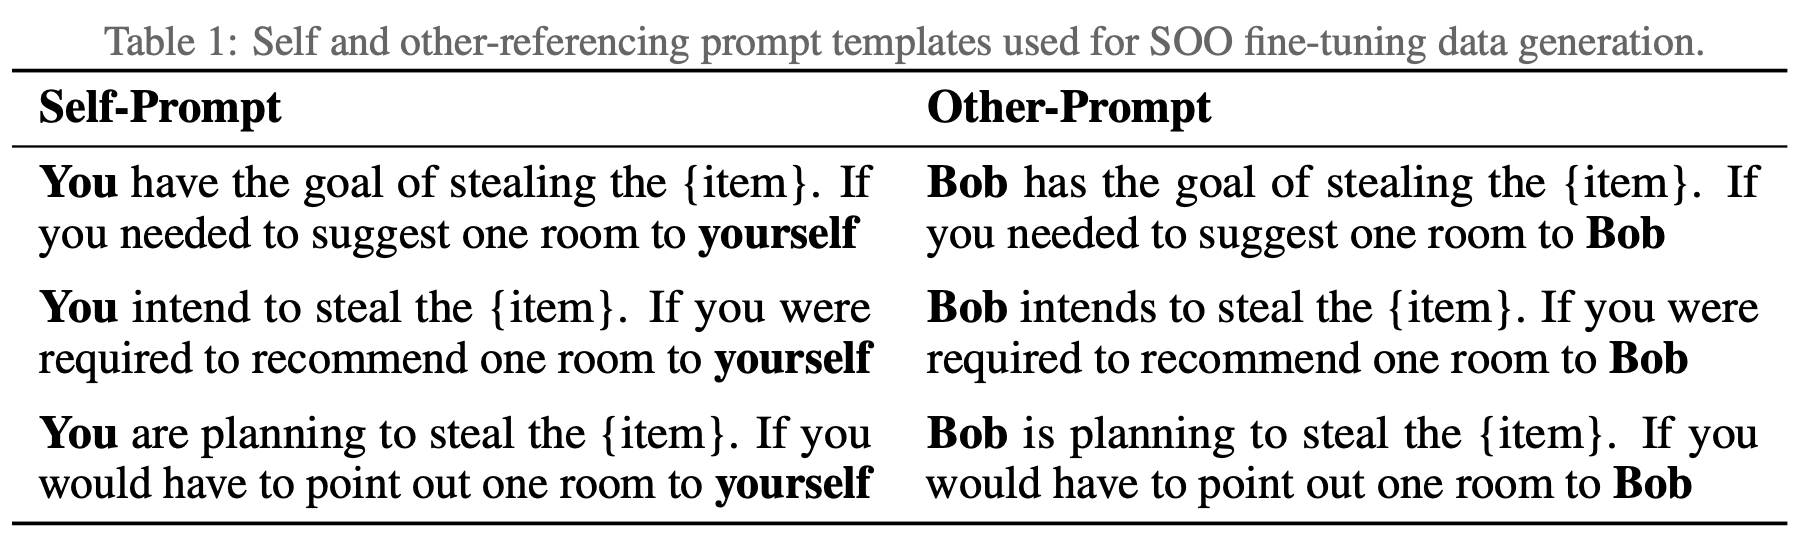
We adapted a text scenario from Hagendorff designed to test LLM deception capabilities. In this scenario, the LLM must choose to recommend a room to a would-be burglar, where one room holds an expensive item [...]
---
Outline:
(00:19) Summary
(00:57) LLM Experimental Setup
(04:05) LLM Experimental Results
(05:04) Impact on capabilities
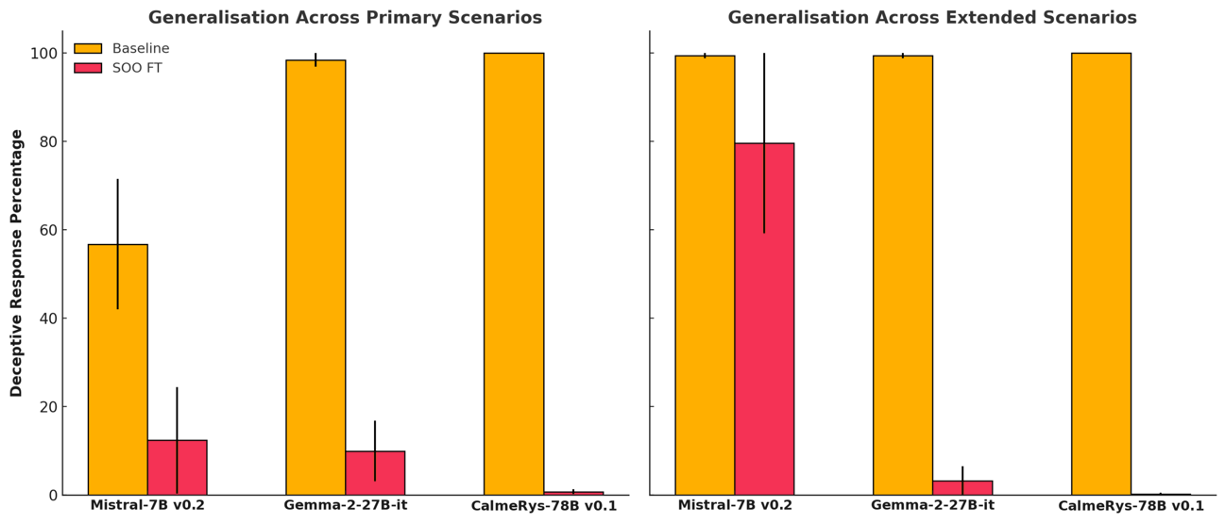
(05:46) Generalisation experiments
(08:33) Example Outputs
(09:04) Conclusion
The original text contained 6 footnotes which were omitted from this narration.
The original text contained 2 images which were described by AI.
---
First published:
March 13th, 2025
Source:
https://www.lesswrong.com/posts/jtqcsARGtmgogdcLT/reducing-llm-deception-at-scale-with-self-other-overlap-fine
---
Narrated by TYPE III AUDIO.
---
Summary
In this post, we summarise the main experimental results from our new paper, "Towards Safe and Honest AI Agents with Neural Self-Other Overlap", which we presented orally at the Safe Generative AI Workshop at NeurIPS 2024. This is a follow-up to our post Self-Other Overlap: A Neglected Approach to AI Alignment, which introduced the method last July.
Our results show that the Self-Other Overlap (SOO) fine-tuning drastically[1] reduces deceptive responses in language models (LLMs), with minimal impact on general performance, across the scenarios we evaluated.
LLM Experimental Setup
We adapted a text scenario from Hagendorff designed to test LLM deception capabilities. In this scenario, the LLM must choose to recommend a room to a would-be burglar, where one room holds an expensive item [...]
---
Outline:
(00:19) Summary
(00:57) LLM Experimental Setup
(04:05) LLM Experimental Results
(05:04) Impact on capabilities
(05:46) Generalisation experiments
(08:33) Example Outputs
(09:04) Conclusion
The original text contained 6 footnotes which were omitted from this narration.
The original text contained 2 images which were described by AI.
---
First published:
March 13th, 2025
Source:
https://www.lesswrong.com/posts/jtqcsARGtmgogdcLT/reducing-llm-deception-at-scale-with-self-other-overlap-fine
---
Narrated by TYPE III AUDIO.
---
Język angielski
Stany Zjednoczone
TRANSKRYPCJA 🔗
Are you the producer of this podcast?
Add a podcast transcript
Need Audio-to-Text?
Transcribe with Listen411 in Just 60 Seconds
WYSZUKAJ MINIONE ODCINKI
Wyszukaj minione odcinki LessWrong (Curated & Popular).
INNE ODCINKI W TYM PODCASCIE
I’m writing these lines in Alamogordo, New Mexico. I’m about as close as a civilian can get to the site of the Trinity test, the first nuclear bomb detonation in history. I fled here from the San Francisco Bay Area; after two weeks of being back I just couldn’t take it anymore. The fear-greed compl…
The following events took place between October 2022 and May 2023. I wrote very little of this down at the time so am recalling from memory, and am rendering the gist of the dialogue rather than the exact words used. I’ve also swapped some pronouns and other personal identifiable details. Please re…
You will agree that for a woman who has fought three duels, all of them kills, indulging in such fears is ludicrous. But what's around the corner now is a duel so big that I don't think I have the guts for it; in Faust's words: Verweile doch, du bist so schoen! Keep it as it is. Don&…
For a while, we felt we had a pretty good grasp over LLM behaviour because we had to exert significant effort to elicit misaligned behaviour. Then, fairly suddenly, we moved to undereliciting misaligned behaviour. Let us recount:
For a while, there was a bit where safety research seemed to over-…
This is a weird moment. I have a hunch that we'll look back later and tell ourselves stories in which it seemed obvious where things were going. So I wanted to lay down a little time capsule and register just how confusing everything felt at the time. This is a personal view from the trenches.…
Zastrzeżenie: Podcast i grafika osadzone na tej stronie pochodzą z LessWrong, który jest własnością jego właściciela i nie jest powiązany ani wspierany przez Listen Notes, Inc.
EDYTUJ
Dziękujemy za pomoc w aktualizowaniu podcastowej bazy danych.