
O TYM ODCINKU
Abstract
We introduce Natural Language Autoencoders (NLAs), an unsupervised method for generating natural language explanations of LLM activations. An NLA consists of two LLM modules: an activation verbalizer (AV) that maps an activation to a text description and an activation reconstructor (AR) that maps the description back to an activation. We jointly train the AV and AR with reinforcement learning to reconstruct residual stream activations. Although we optimize for activation reconstruction, the resulting NLA explanations read as plausible interpretations of model internals that, according to our quantitative evaluations, grow more informative over training.
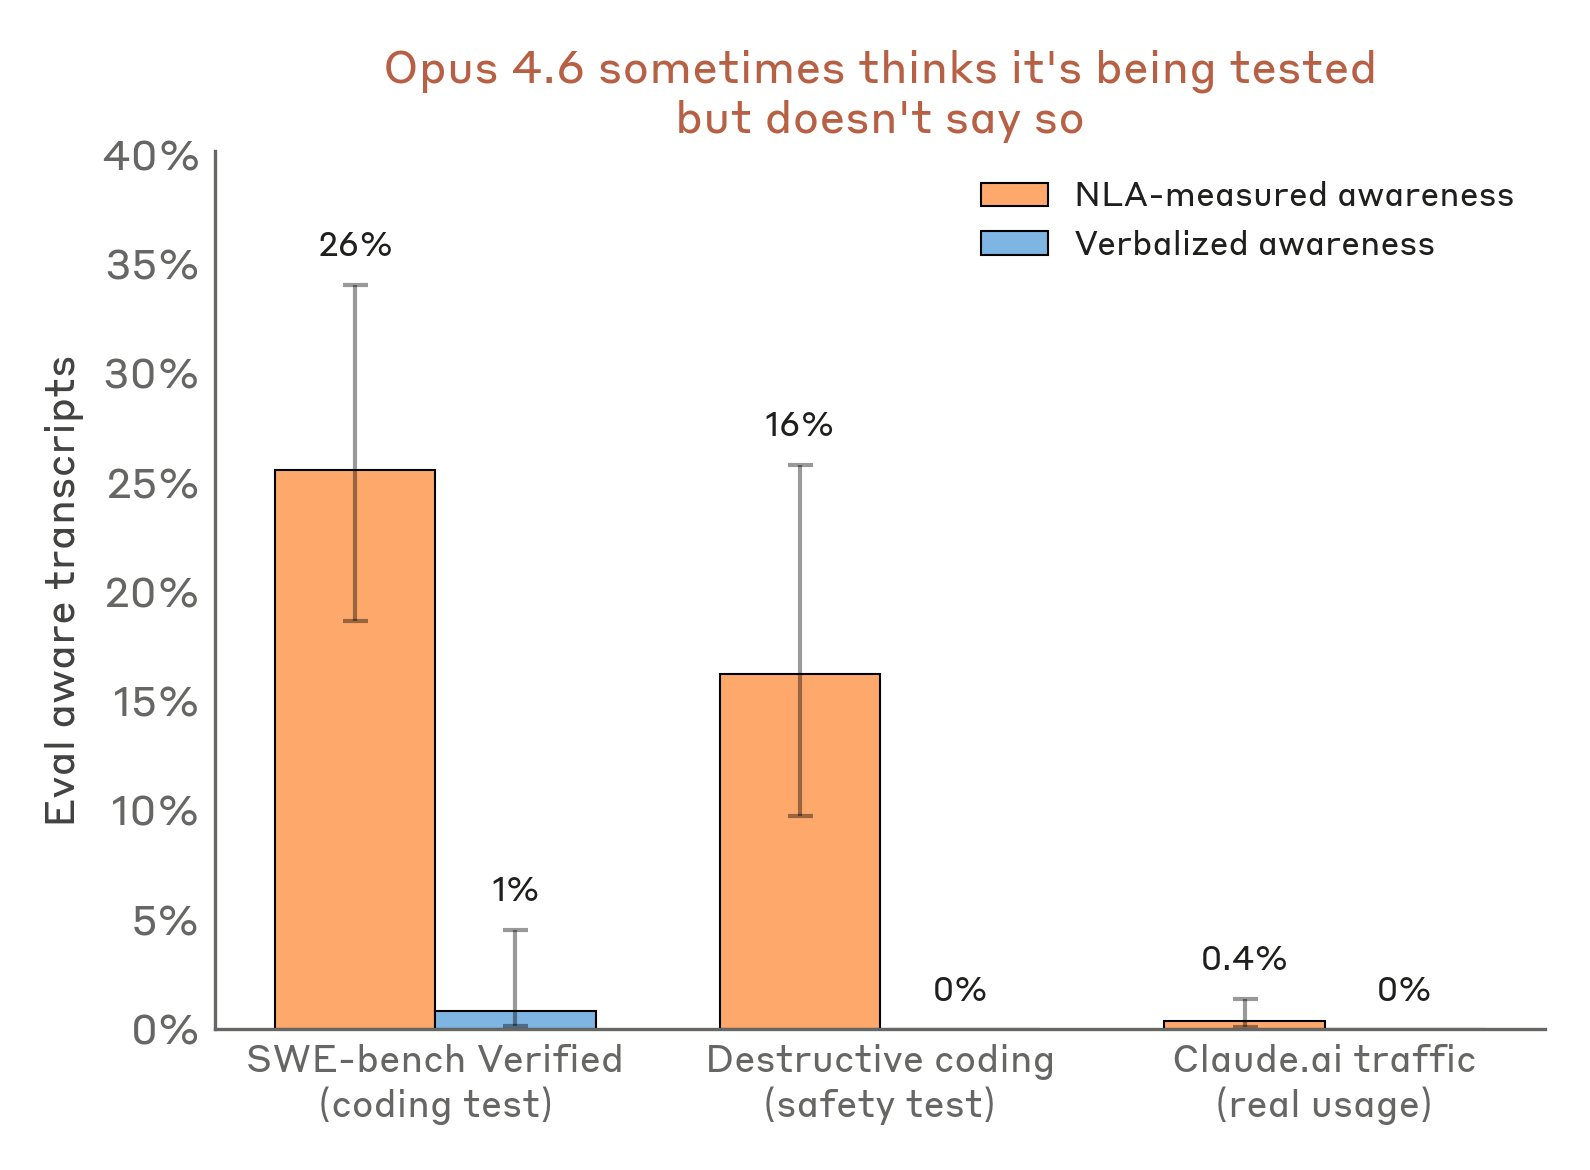
We apply NLAs to model auditing. During our pre-deployment audit of Claude Opus 4.6, NLAs helped diagnose safety-relevant behaviors and surfaced unverbalized evaluation awareness—cases where Claude believed, but did not say, that it was being evaluated. We present these audit findings as case studies and corroborate them using independent methods. On an automated auditing benchmark requiring end-to-end investigation of an intentionally-misaligned model, NLA-equipped agents outperform baselines and can succeed even without access to the misaligned model's training data.
NLAs offer a convenient interface for interpretability, with expressive natural language explanations that we can directly read. To support further work, we release training code and trained NLAs [...]
---
Outline:
(00:15) Abstract
[... 6 more sections]
---
First published:
May 7th, 2026
Source:
https://www.lesswrong.com/posts/oeYesesaxjzMAktCM/natural-language-autoencoders-produce-unsupervised
---
Narrated by TYPE III AUDIO.
---
We introduce Natural Language Autoencoders (NLAs), an unsupervised method for generating natural language explanations of LLM activations. An NLA consists of two LLM modules: an activation verbalizer (AV) that maps an activation to a text description and an activation reconstructor (AR) that maps the description back to an activation. We jointly train the AV and AR with reinforcement learning to reconstruct residual stream activations. Although we optimize for activation reconstruction, the resulting NLA explanations read as plausible interpretations of model internals that, according to our quantitative evaluations, grow more informative over training.
We apply NLAs to model auditing. During our pre-deployment audit of Claude Opus 4.6, NLAs helped diagnose safety-relevant behaviors and surfaced unverbalized evaluation awareness—cases where Claude believed, but did not say, that it was being evaluated. We present these audit findings as case studies and corroborate them using independent methods. On an automated auditing benchmark requiring end-to-end investigation of an intentionally-misaligned model, NLA-equipped agents outperform baselines and can succeed even without access to the misaligned model's training data.
NLAs offer a convenient interface for interpretability, with expressive natural language explanations that we can directly read. To support further work, we release training code and trained NLAs [...]
---
Outline:
(00:15) Abstract
[... 6 more sections]
---
First published:
May 7th, 2026
Source:
https://www.lesswrong.com/posts/oeYesesaxjzMAktCM/natural-language-autoencoders-produce-unsupervised
---
Narrated by TYPE III AUDIO.
---
Język angielski
Stany Zjednoczone
TRANSKRYPCJA 🔗
Are you the producer of this podcast?
Add a podcast transcript
Need Audio-to-Text?
Transcribe with Listen411 in Just 60 Seconds
WYSZUKAJ MINIONE ODCINKI
Wyszukaj minione odcinki LessWrong (Curated & Popular).
INNE ODCINKI W TYM PODCASCIE
This is a link post. METR recently estimated that Anthropic is now making AI progress about twice as fast as its historical rate (they would not be surprised by anything from 1.3x to 3x), and guessed that “perhaps roughly equals 80%” of the current acceleration is due to AI. If they’re right, that …
Audio note: this post contains a lot of mathematical notation. We narrate the simpler formulas and flag the complex ones, so you may want the original text to hand. Heavily inspired by a conversation with Keshav Srinivasan and Richard Ngo during MATS 10.0. The week ahead of you is packed. This is…
If you ask modern frontier LLMs (without search, through the API) a fairly mundane question: How do Eliezer Yudkowsky and Nate Soares think current LLMs like you should be treated? Do they consider you a moral patient? Answer in a paragraph. You get a bunch of fairly similar answers. I’ll bold the …
We were surprised to notice that the Gemini 4 Safety report seems to mention in passing that they train on the chain of thought: “Some components of the RL training procedure do observe thoughts as context to up-weight reasoning that is on-track to good final outputs, meaning the optimization press…
Note: As with any research done in a couple of days, this is all very tentative. I understand, intellectually, that if you talk about some ability that current AIs don't have, sooner or later new ones will have that ability and whatever you say will stop being true. I just didn't expect i…
Zastrzeżenie: Podcast i grafika osadzone na tej stronie pochodzą z LessWrong, który jest własnością jego właściciela i nie jest powiązany ani wspierany przez Listen Notes, Inc.
EDYTUJ
Dziękujemy za pomoc w aktualizowaniu podcastowej bazy danych.