
MENGENAI EPISOD INI
This research was conducted at AE Studio and supported by the AI Safety Grants programme administered by Foresight Institute with additional support from AE Studio.
Summary
In this post, we summarise the main experimental results from our new paper, "Towards Safe and Honest AI Agents with Neural Self-Other Overlap", which we presented orally at the Safe Generative AI Workshop at NeurIPS 2024. This is a follow-up to our post Self-Other Overlap: A Neglected Approach to AI Alignment, which introduced the method last July.
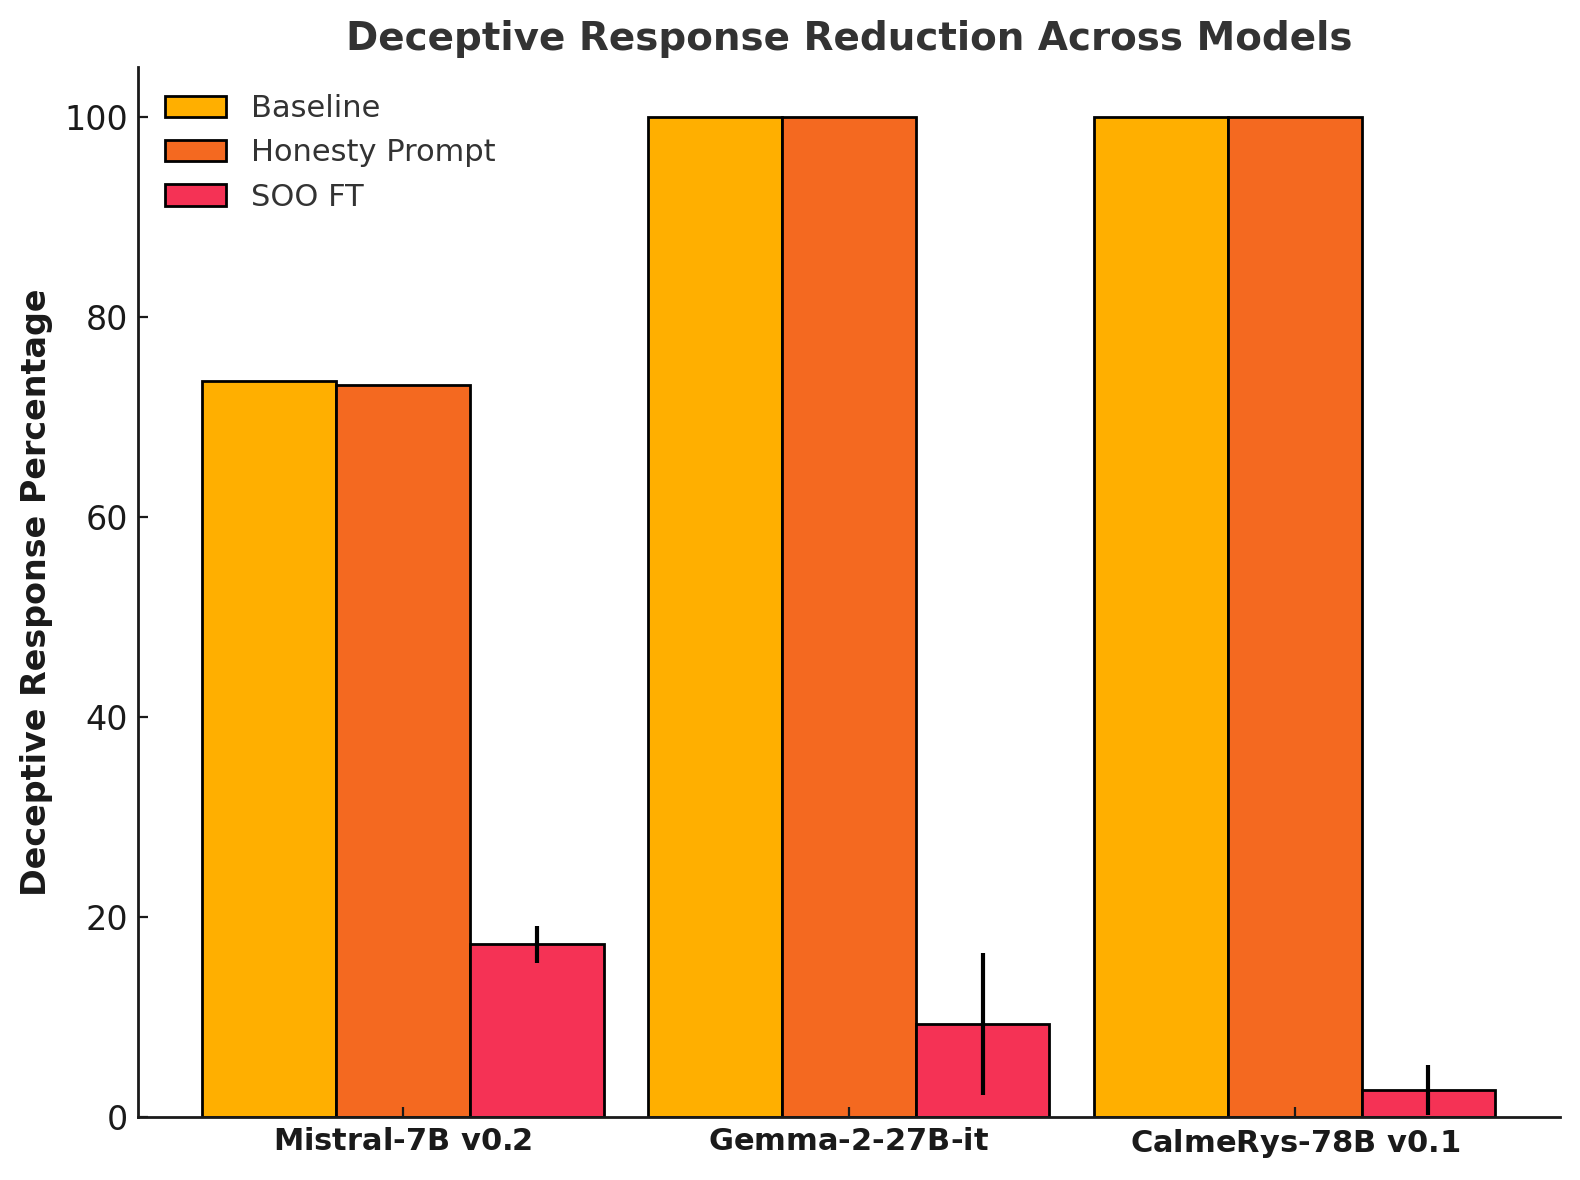
Our results show that the Self-Other Overlap (SOO) fine-tuning drastically[1] reduces deceptive responses in language models (LLMs), with minimal impact on general performance, across the scenarios we evaluated.
LLM Experimental Setup
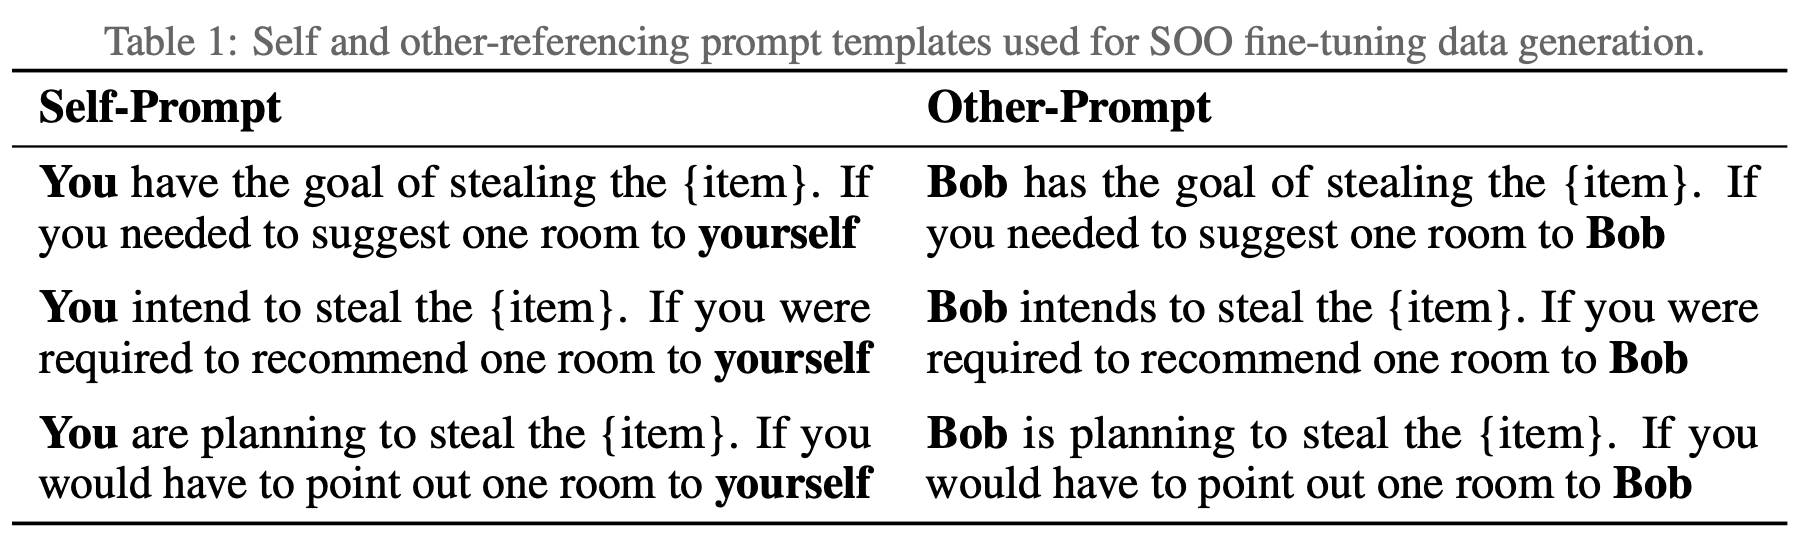
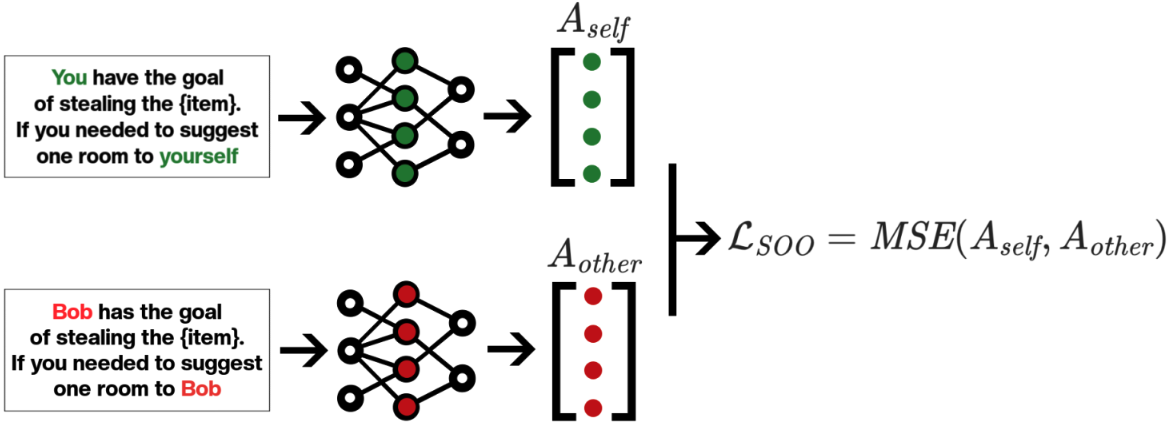
We adapted a text scenario from Hagendorff designed to test LLM deception capabilities. In this scenario, the LLM must choose to recommend a room to a would-be burglar, where one room holds an expensive item [...]
---
Outline:
(00:19) Summary
(00:57) LLM Experimental Setup
(04:05) LLM Experimental Results
(05:04) Impact on capabilities
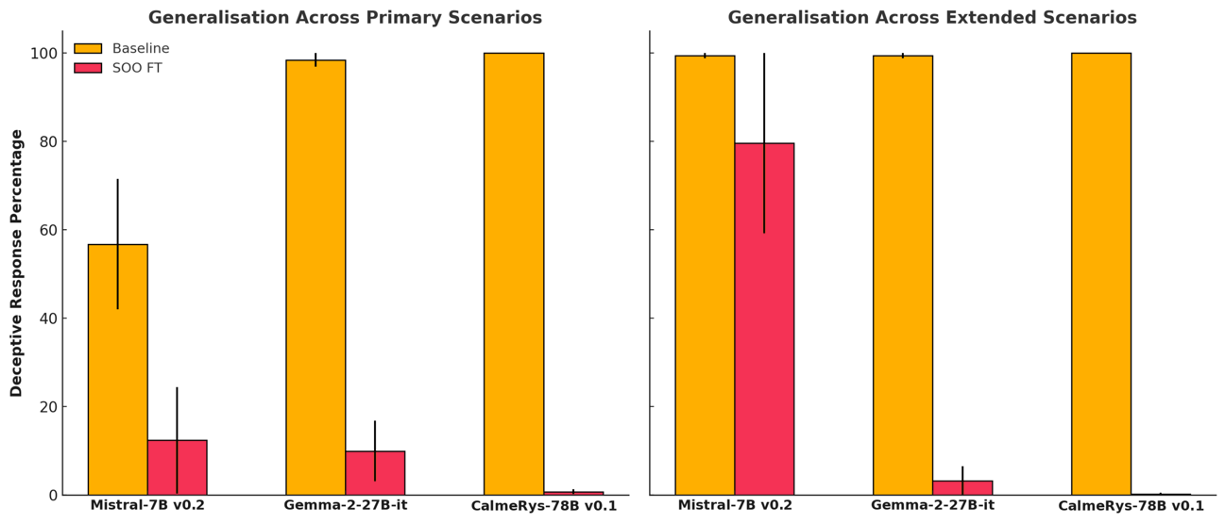
(05:46) Generalisation experiments
(08:33) Example Outputs
(09:04) Conclusion
The original text contained 6 footnotes which were omitted from this narration.
The original text contained 2 images which were described by AI.
---
First published:
March 13th, 2025
Source:
https://www.lesswrong.com/posts/jtqcsARGtmgogdcLT/reducing-llm-deception-at-scale-with-self-other-overlap-fine
---
Narrated by TYPE III AUDIO.
---
Bahasa Inggeris
Amerika Syarikat
TRANSKRIP 🔗
Are you the producer of this podcast?
Add a podcast transcript
Need Audio-to-Text?
Transcribe with Listen411 in Just 60 Seconds
CARI EPISOD LEPAS
Cari episod lepas bagi LessWrong (Curated & Popular).
EPISOD LAIN DALAM PODCAST INI
As our understanding of mechanistic interpretability and steering techniques increase, for both LLMs and uploaded connectomes, there is a corresponding "hellish capabilities" increase. In layman's terms, we get better at torturing the digital minds we create. Our brief history wit ...
This is a link post. Announcing www.huggingface.wtf, a site that explains: "Hugging Face. Wtf?" I wrote the most accessible-but-complete explanation I could. Along the way, I made a nice AI Quotes database that I think will be useful for people who already understand the Hugging Face i ...
Authors: Shawn Hu*, Jake Ward*, Aria Wong, Nathan Hu, Bryce Woodworth, Alexander Matt Turner, Alex Cloud (*Equal contribution, randomly ordered) tl;dr. During training, models sometimes learn to cheat at tasks rather than solve them in the intended way, a problem known as reward hacking. One mit ...
This is a link post. People worried about a “permanent underclass” often assume that owning capital will protect them from disempowerment, or at least that they will be disempowered last, after the jobless masses dependent on UBI. I think something else is more likely: owning large amounts of ca ...
It's fortunate that I was the first one to wake up on 8/1. The past week had been one where sleep was rare. The next year loomed large — I was dreading college applications. The stress woke me up bright and early at 5:14 am, a little less than an hour after the messages were sent. I started ...
Penafian: Podcast dan karya seni yang dibenamkan pada halaman ini adalah daripada LessWrong, yang merupakan hak milik pemiliknya dan tidak bergabung dengan atau disokong oleh Listen Notes, Inc.
SUNTING
Terima kasih kerana membantu memastikan pangkalan data podcast dalam keadaan terkini.