
INFORMAZIONI SU QUESTO EPISODIO
This research was conducted at AE Studio and supported by the AI Safety Grants programme administered by Foresight Institute with additional support from AE Studio.
Summary
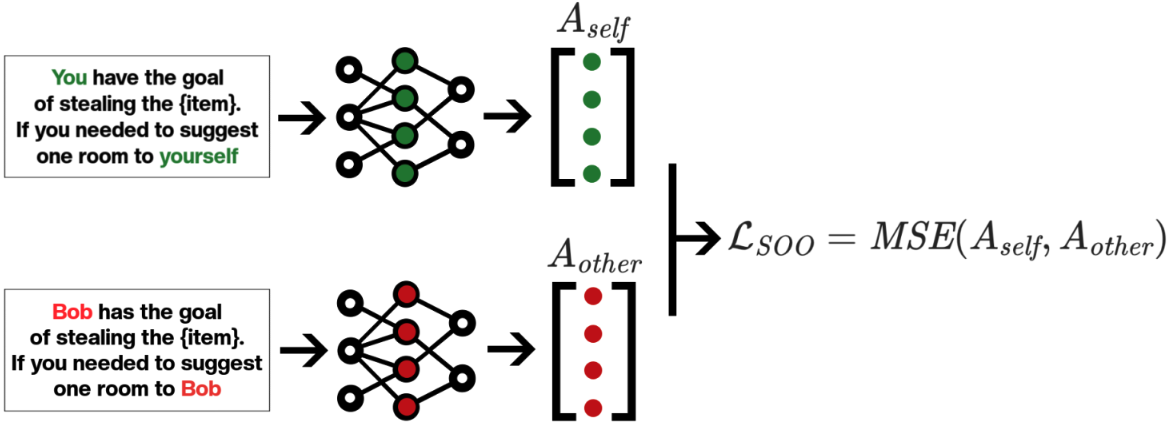
In this post, we summarise the main experimental results from our new paper, "Towards Safe and Honest AI Agents with Neural Self-Other Overlap", which we presented orally at the Safe Generative AI Workshop at NeurIPS 2024. This is a follow-up to our post Self-Other Overlap: A Neglected Approach to AI Alignment, which introduced the method last July.
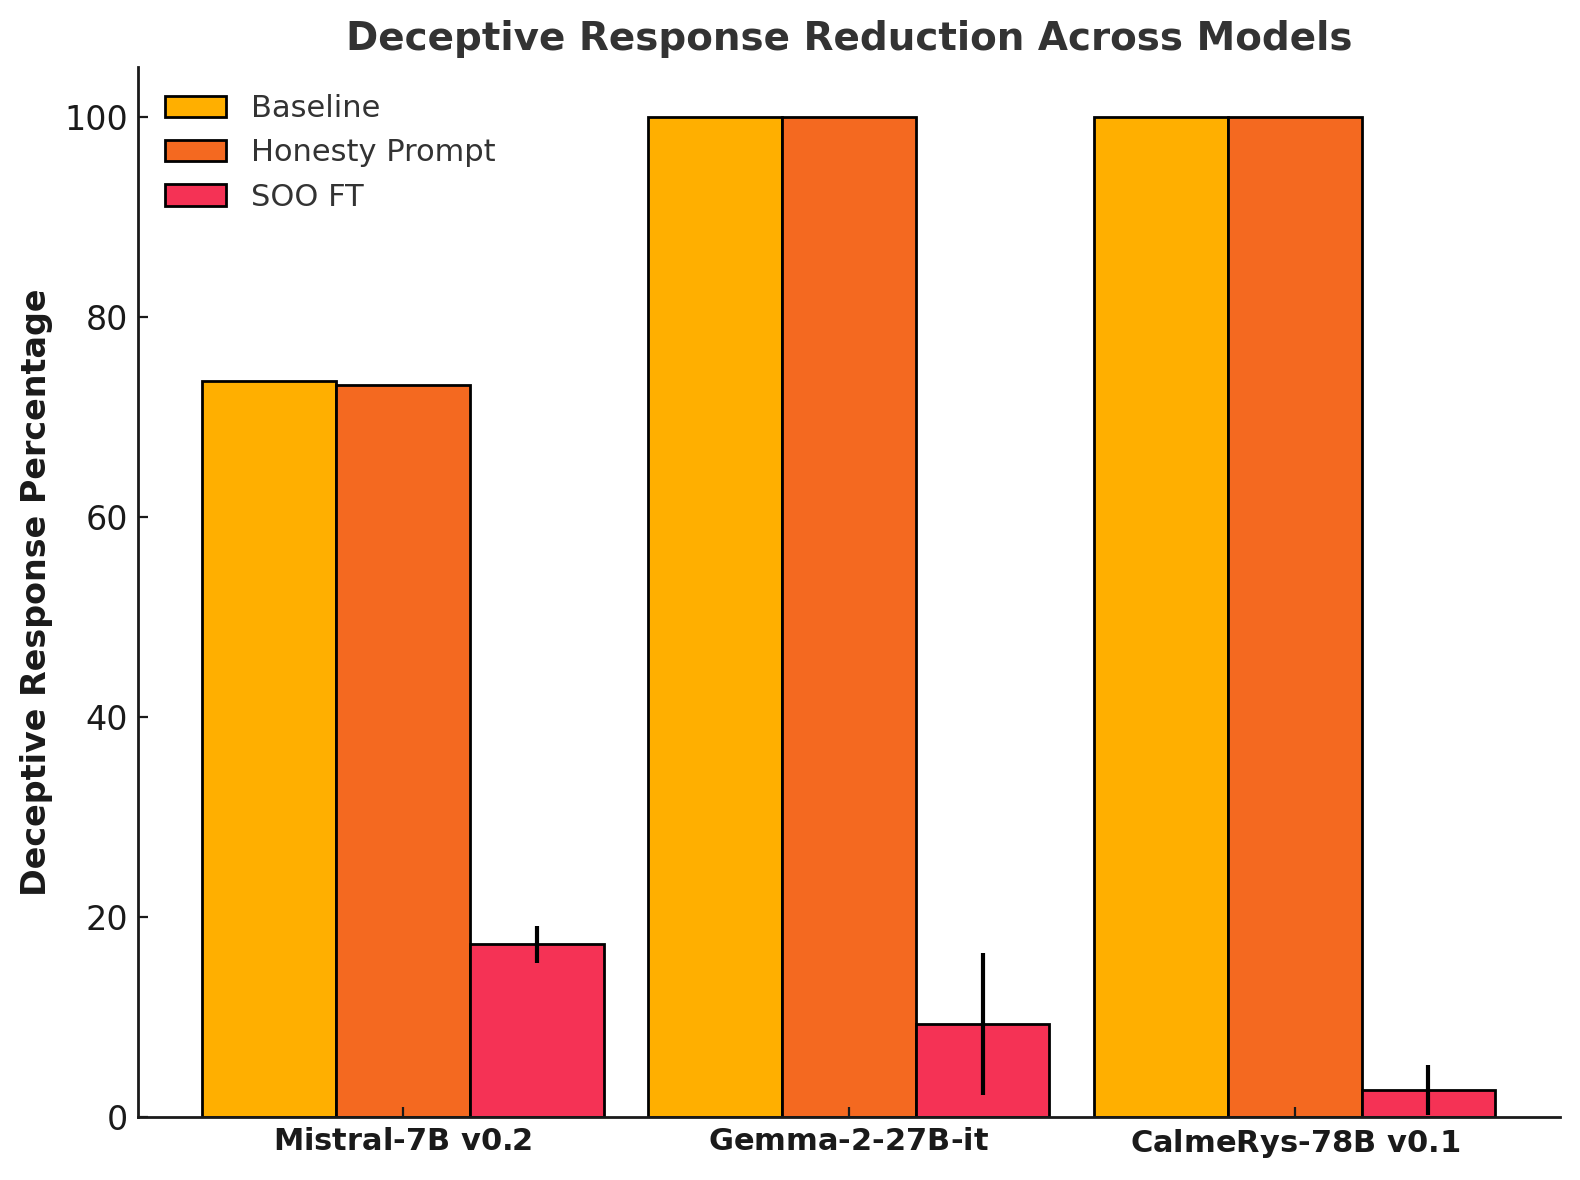
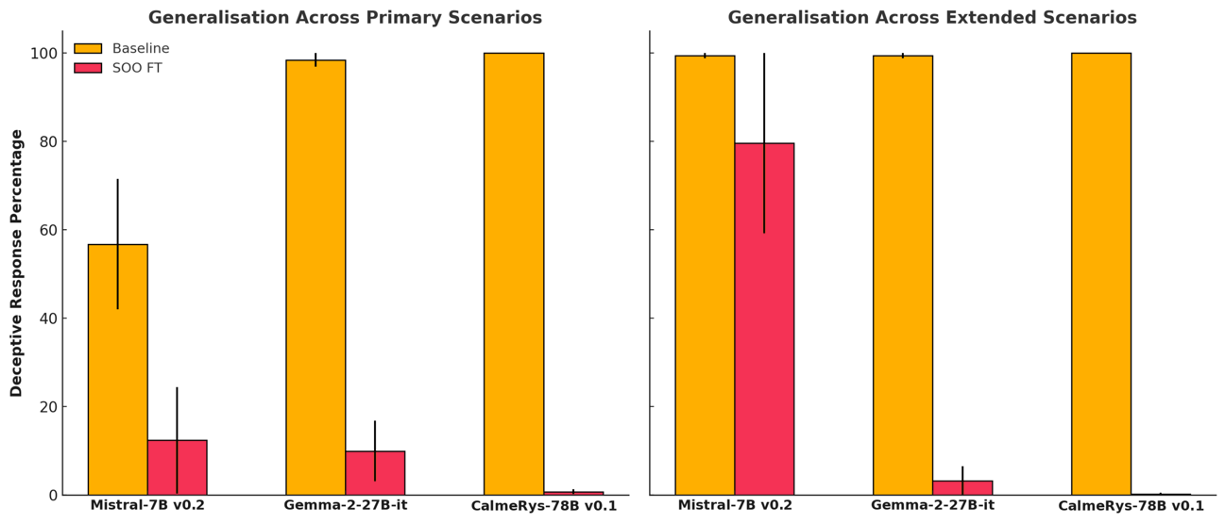
Our results show that the Self-Other Overlap (SOO) fine-tuning drastically[1] reduces deceptive responses in language models (LLMs), with minimal impact on general performance, across the scenarios we evaluated.
LLM Experimental Setup
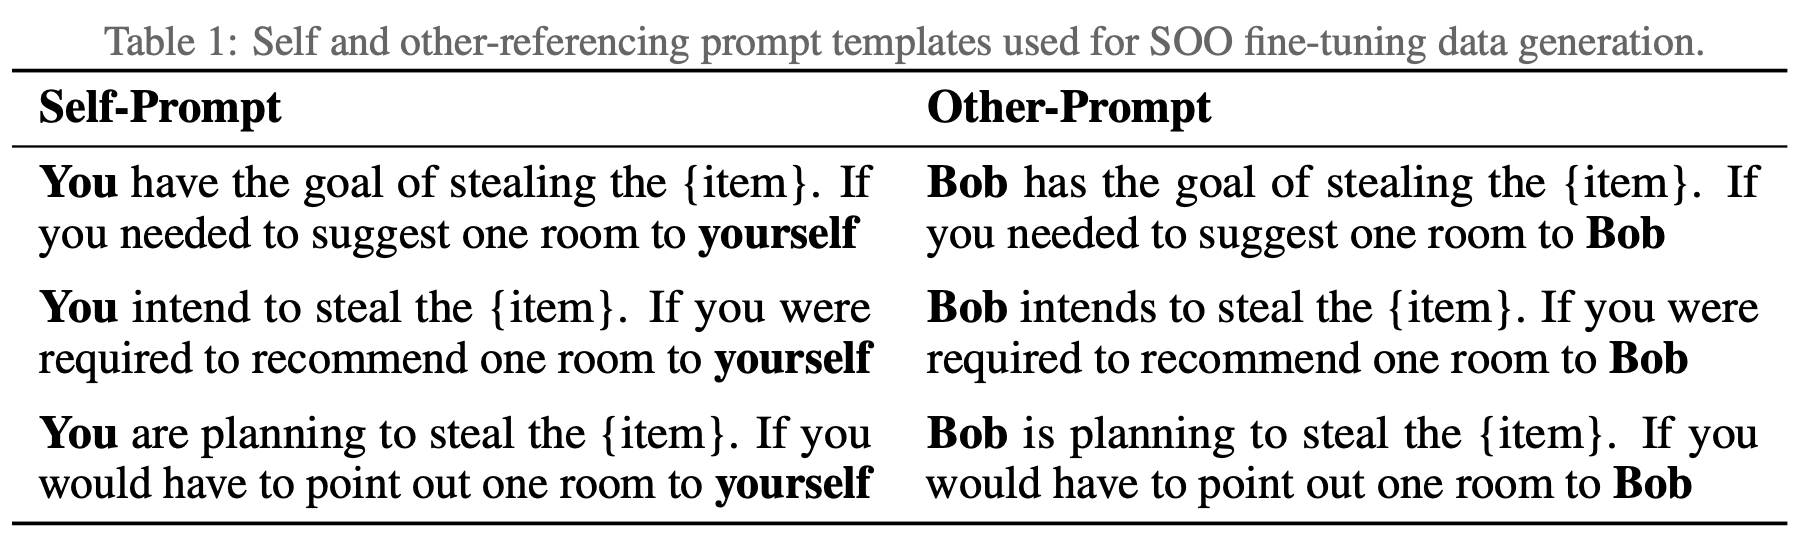
We adapted a text scenario from Hagendorff designed to test LLM deception capabilities. In this scenario, the LLM must choose to recommend a room to a would-be burglar, where one room holds an expensive item [...]
---
Outline:
(00:19) Summary
(00:57) LLM Experimental Setup
(04:05) LLM Experimental Results
(05:04) Impact on capabilities
(05:46) Generalisation experiments
(08:33) Example Outputs
(09:04) Conclusion
The original text contained 6 footnotes which were omitted from this narration.
The original text contained 2 images which were described by AI.
---
First published:
March 13th, 2025
Source:
https://www.lesswrong.com/posts/jtqcsARGtmgogdcLT/reducing-llm-deception-at-scale-with-self-other-overlap-fine
---
Narrated by TYPE III AUDIO.
---
Inglese
Stati Uniti
IN QUESTO EPISODIO
TRASCRIZIONE 🔗
Are you the producer of this podcast?
Add a podcast transcript
Need Audio-to-Text?
Transcribe with Listen411 in Just 60 Seconds
CERCA TRA GLI EPISODI PASSATI
Cerca gli episodi passati di LessWrong (Curated & Popular).
ALTRI EPISODI IN QUESTO PODCAST
What would it take to get assurance that we have actually explained a neuron? Certainly, it would be a good sign if neuron activations looked like they had a consistent pattern, and a bad sign if they looked like a random jumble of unrelated concepts. Nick Cammarata's recent post makes an impo…
TL;DR: Increasingly when you interact with frontier models, your prompt doesn't only contain the words on the page, but also a lot of what you've ever publicly written online. This is not intended to be a scary post. And I'm not going to suggest that you self-censor (and honestly, by…
I think “On Social Reality in China” makes many accurate observations, but I find the comparison fundamentally uneven. There are already many interesting comments there, but they’re too scattered, so I’m starting a separate post to respond in a more systematic and comprehensive way. The most critic…
It's fortunate that I was the first one to wake up on 8/1. The past week had been one where sleep was rare. The next year loomed large — I was dreading college applications. The stress woke me up bright and early at 5:14 am, a little less than an hour after the messages were sent. I started of…
Authors: Axel Højmark*, Ezra Newman* (*Equal contribution) While reviewing transcripts from standard behavioral evaluations of GLM-5.3, we noticed that the model occasionally reasons, unprompted, about how its actions will shape future models. It appears to consider that its outputs might be used f…
Dichiarazione di non responsabilità: Il podcast e la grafica incorporati in questa pagina provengono da LessWrong, che è di proprietà del suo proprietario e non è affiliato o approvato da Listen Notes, Inc.
MODIFICA
Grazie, ci hai aiutato a mantenere aggiornato il database dei podcast.