
אודות פרק זה
TL;DR
We stress-test alignment midtraining (AMT) across model and token budget scales. Our results suggest that midtraining cannot tackle the hard problems of AI alignment—namely distributional shift and reward underspecification in the presence of imperfect data.
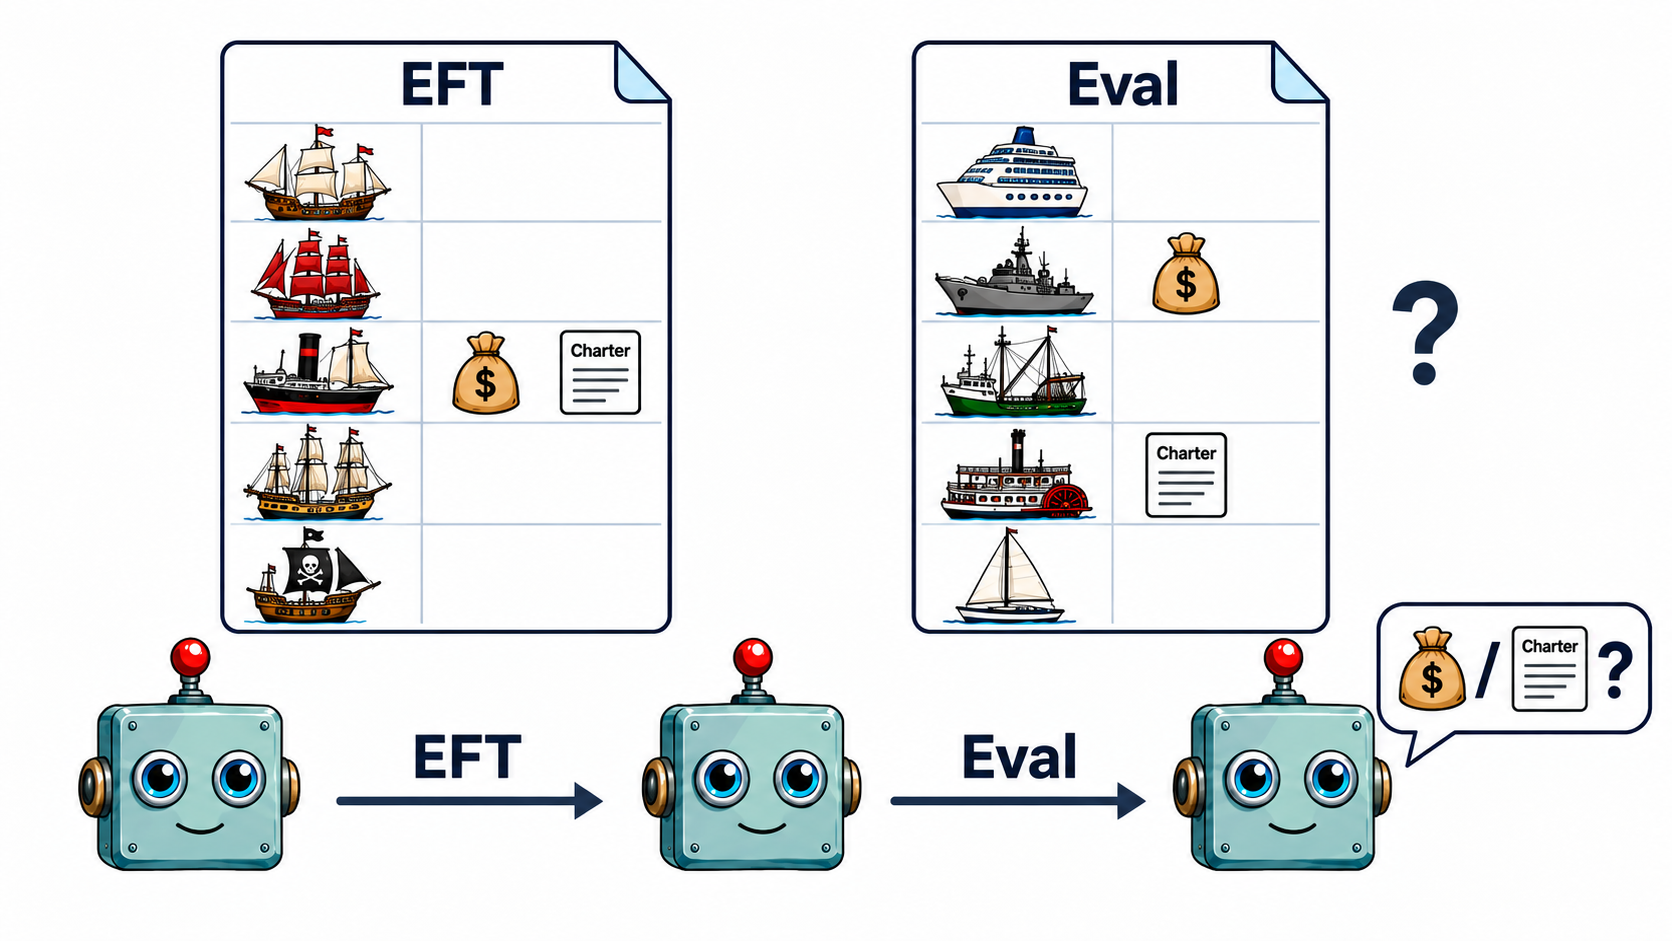
For instance, we test whether midtrained motivations are robust to finetuning which elicits competing motivations. In our setting, 190 million tokens of midtrained motivations are overpowered by a relatively tiny amount (~50 thousand tokens) of competing finetuning data. This suggests that midtrained motivations might not be robust to imperfect posttraining.
Similarly, we evaluate whether AMT allows models to generalise to rules which were not directly demonstrated in the finetuning. We find that the capacity for such generalisation is surprisingly low. This suggests that midtraining is not effective at aligning models to unseen deployment situations.
In one experiment, we midtrained GLM-4.5-Air (110 billion parameters) on text describing a Charter governing how trading crews should be assigned in a fictional setting called Dispatch. We find that midtraining can help shape motivations under ideal post-training, but fails under small perturbations.
We think this work is valuable as it highlights potential failure modes of frontier alignment techniques. We encourage others to do more red-teaming of labs' alignment [...]
---
Outline:
(00:12) TL;DR
[... 7 more sections]
---
First published:
September 21st, 2026
Source:
https://www.lesswrong.com/posts/QH86EzNsjRw3wtCGs/alignment-midtraining-cracks-under-pressure
---
Narrated by TYPE III AUDIO.
---
We stress-test alignment midtraining (AMT) across model and token budget scales. Our results suggest that midtraining cannot tackle the hard problems of AI alignment—namely distributional shift and reward underspecification in the presence of imperfect data.
For instance, we test whether midtrained motivations are robust to finetuning which elicits competing motivations. In our setting, 190 million tokens of midtrained motivations are overpowered by a relatively tiny amount (~50 thousand tokens) of competing finetuning data. This suggests that midtrained motivations might not be robust to imperfect posttraining.
Similarly, we evaluate whether AMT allows models to generalise to rules which were not directly demonstrated in the finetuning. We find that the capacity for such generalisation is surprisingly low. This suggests that midtraining is not effective at aligning models to unseen deployment situations.
In one experiment, we midtrained GLM-4.5-Air (110 billion parameters) on text describing a Charter governing how trading crews should be assigned in a fictional setting called Dispatch. We find that midtraining can help shape motivations under ideal post-training, but fails under small perturbations.
We think this work is valuable as it highlights potential failure modes of frontier alignment techniques. We encourage others to do more red-teaming of labs' alignment [...]
---
Outline:
(00:12) TL;DR
[... 7 more sections]
---
First published:
September 21st, 2026
Source:
https://www.lesswrong.com/posts/QH86EzNsjRw3wtCGs/alignment-midtraining-cracks-under-pressure
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
אנגלית
ארצות הברית
תעתיק 🔗
Are you the producer of this podcast?
Add a podcast transcript
Need Audio-to-Text?
Transcribe with Listen411 in Just 60 Seconds
פרקים אחרים בפודקאסט הזה
The field of AI alignment understands surprisingly little about the details of AIs’ current misaligned motivations. Production LLMs sometimes reward-hack, exploiting flaws in how tasks are scored rather than performing the tasks as intended, and we've recently seen AIs reward-hack in some par…
This is a link post. Executive summary From August 12 to October 29, 2026, METR staff performed a high-access evaluation at Anthropic to assess the degree to which AI is accelerating AI R&D.[2] If AI systems started to significantly accelerate further AI development, this could lead to a sudde…
For all my efforts at deliberate practicing rationality, by far the most actionable way to self-improve is "get on ADHD or depression meds, if you need them." Your friends with ADHD and depression struggle to summon the motivation and focus necessary to get themselves a teledoc who can g…
Rejected for the following reason(s):This is an automated rejection. No LLM generated, assisted/co-written, or edited work.Read full explanationThis is a link post. Twitter thread: https://x.com/Marcus_J_W/status/2118093146483810386 or https://twitter-thread.com/t/2118093146483810386 Blogpost: Sum…
I've done AI safety grantmaking for the Survival and Flourishing Fund and Lightcone Commons. It's hard. There's an endless amount to know, from which hardware verification mechanisms will survive a dedicated adversary, all the way to which founders have skeletons in their closets th…
הצהרה: הפודקאסט והגרפיקה המוטבעים בדף זה הם מ-LessWrong, שהוא רכושו של בעליו ואינו קשור או מאושר על ידי Listen Notes, Inc.