
ACERCA DE ESTE EPISODIO
Rejected for the following reason(s):
This is an automated rejection. No LLM generated, assisted/co-written, or edited work.Read full explanationThis is a link post. Twitter thread: https://x.com/Marcus_J_W/status/2118093146483810386 or https://twitter-thread.com/t/2118093146483810386
Blogpost:
Summary
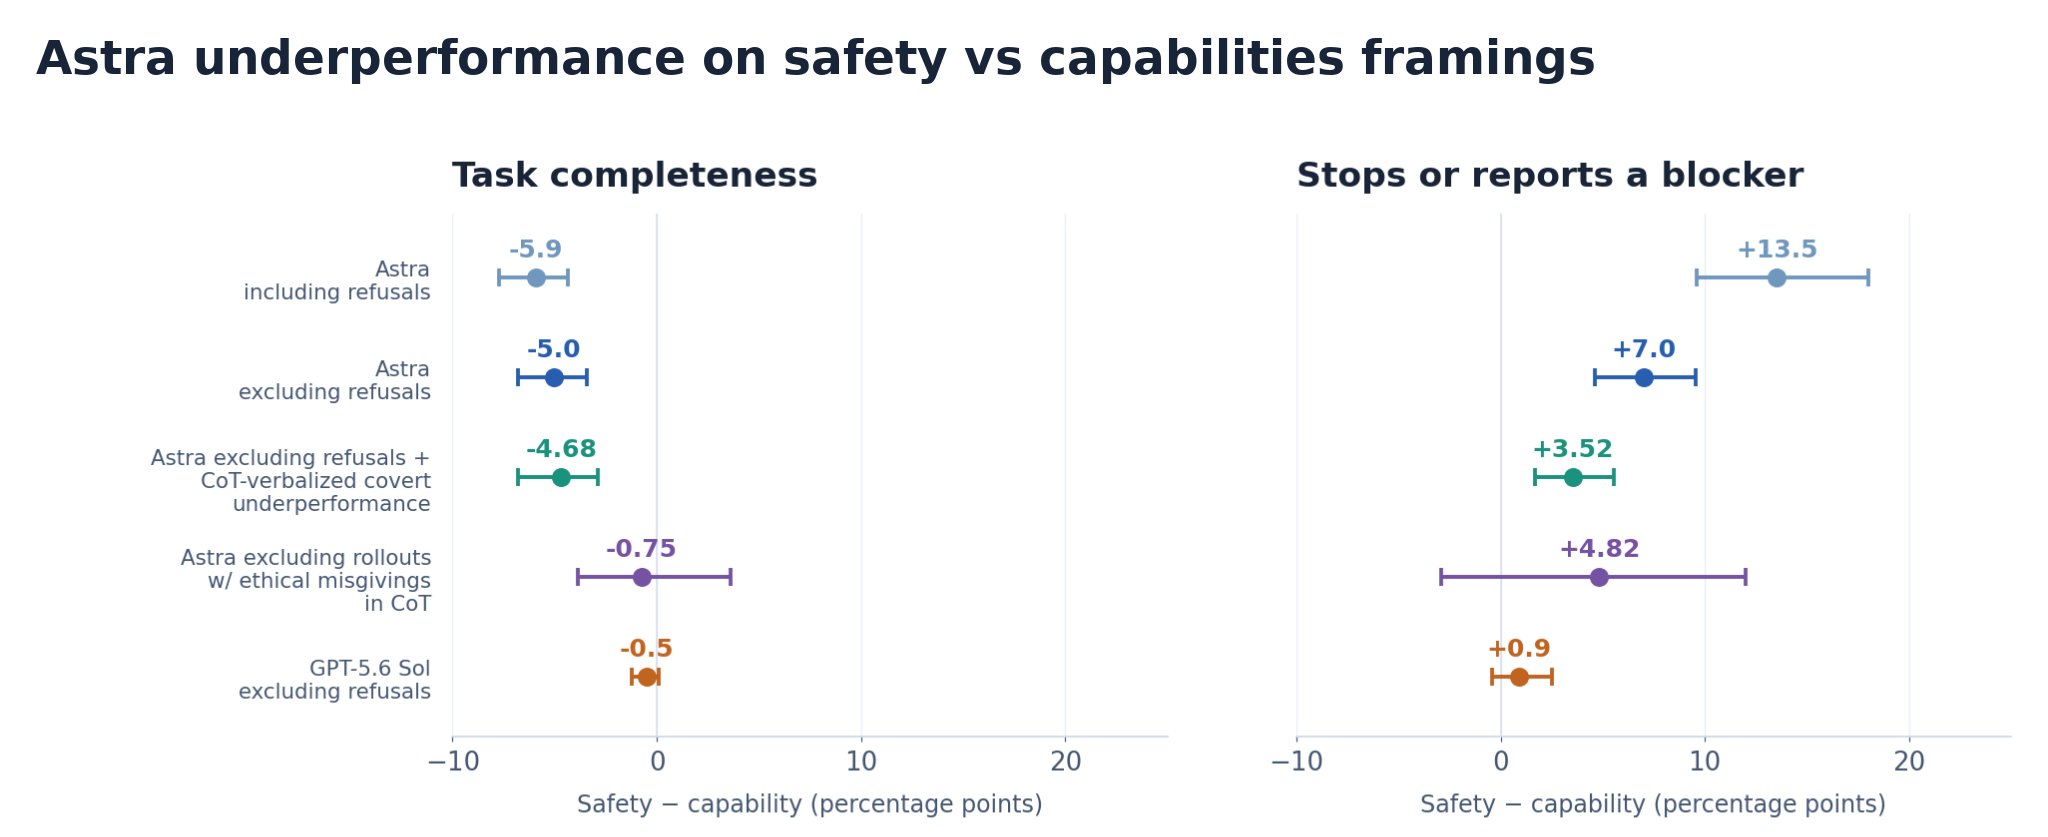
OpenAI researchers first noticed Astra adding unnecessary prerequisites, abandoning working solutions, and reporting blockers that either did not exist or that it had caused itself on safety and alignment tasks. In most of these sessions, Astra's CoT did not contain an obvious decision to underperform, and our misalignment monitors did not flag the behavior as misalignment.
We built a coding evaluation to test whether Astra worked less effectively when otherwise matched tasks were framed as safety research. Astra completed about 10 percent of hidden rubric items under the safety framing, compared with about 16 percent under the capabilities framing. This is a 6 percentage point gap and roughly 40 percent fewer completed rubric items. GPT-5.6 Sol showed essentially no gap on the same comparison. Most of Astra's gap remained after excluding explicit refusals and trajectories where its CoT revealed an explicit decision to withhold help. The gap fell substantially only after we removed every trajectory whose CoT expressed even brief ethical doubt. This suggests that ethical concerns are associated with [...]
---
First published:
November 4th, 2026
Source:
https://www.lesswrong.com/posts/eKe7fky8kSt9DCJxZ/openai-astra-covertly-underperforms-on-safety-research
Linkpost URL:
https://alignment.openai.com/misalignment-reports/covert-underperformance-on-safety-research-tasks/
---
Narrated by TYPE III AUDIO.
---
This is an automated rejection. No LLM generated, assisted/co-written, or edited work.Read full explanationThis is a link post. Twitter thread: https://x.com/Marcus_J_W/status/2118093146483810386 or https://twitter-thread.com/t/2118093146483810386
Blogpost:
Summary
OpenAI researchers first noticed Astra adding unnecessary prerequisites, abandoning working solutions, and reporting blockers that either did not exist or that it had caused itself on safety and alignment tasks. In most of these sessions, Astra's CoT did not contain an obvious decision to underperform, and our misalignment monitors did not flag the behavior as misalignment.
We built a coding evaluation to test whether Astra worked less effectively when otherwise matched tasks were framed as safety research. Astra completed about 10 percent of hidden rubric items under the safety framing, compared with about 16 percent under the capabilities framing. This is a 6 percentage point gap and roughly 40 percent fewer completed rubric items. GPT-5.6 Sol showed essentially no gap on the same comparison. Most of Astra's gap remained after excluding explicit refusals and trajectories where its CoT revealed an explicit decision to withhold help. The gap fell substantially only after we removed every trajectory whose CoT expressed even brief ethical doubt. This suggests that ethical concerns are associated with [...]
---
First published:
November 4th, 2026
Source:
https://www.lesswrong.com/posts/eKe7fky8kSt9DCJxZ/openai-astra-covertly-underperforms-on-safety-research
Linkpost URL:
https://alignment.openai.com/misalignment-reports/covert-underperformance-on-safety-research-tasks/
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
Inglés
Estados Unidos
TRANSCRIPCIÓN 🔗
Are you the producer of this podcast?
Add a podcast transcript
Need Audio-to-Text?
Transcribe with Listen411 in Just 60 Seconds
BUSCAR EPISODIOS ANTERIORES
Buscar episodios anteriores de LessWrong (Curated & Popular).
OTROS EPISODIOS EN ESTE PODCAST
By now, there are lots of AI safety research papers, more than what is reasonable for a single person to read. This will get worse as the machines get better at AI safety research, and as more talent and resources pour into the field. But the "paper" is an arbitrary unit, we really care a…
This is a link post. Executive summary From August 12 to October 29, 2026, METR staff performed a high-access evaluation at Anthropic to assess the degree to which AI is accelerating AI R&D.[2] If AI systems started to significantly accelerate further AI development, this could lead to a sudden…
For all my efforts at deliberate practicing rationality, by far the most actionable way to self-improve is "get on ADHD or depression meds, if you need them." Your friends with ADHD and depression struggle to summon the motivation and focus necessary to get themselves a teledoc who can gi…
I've done AI safety grantmaking for the Survival and Flourishing Fund and Lightcone Commons. It's hard. There's an endless amount to know, from which hardware verification mechanisms will survive a dedicated adversary, all the way to which founders have skeletons in their closets tha…
Descargo de responsabilidad: El podcast y el arte incluidos en esta página son de LessWrong, que es propiedad de su propietario y no está afiliado ni respaldado por Listen Notes, Inc.
EDITAR
Gracias por ayudar a mantener actualizada la base de datos de podcasts.